This session has finished
End-to-End Snowflake
Sunday, 12 July · 12:00 PM IST · Durgesh Yadav · Sr. Data Engineer, 7-Eleven
Registration is closed because it already ran live. The full recording and every resource from it are on the shelf below — and the next live session is open now.
Next live webinar · free seat
Break Into Data Engineering From a tech or non-tech start
Saturday, 24 October · 12:30 PM IST
What this session became
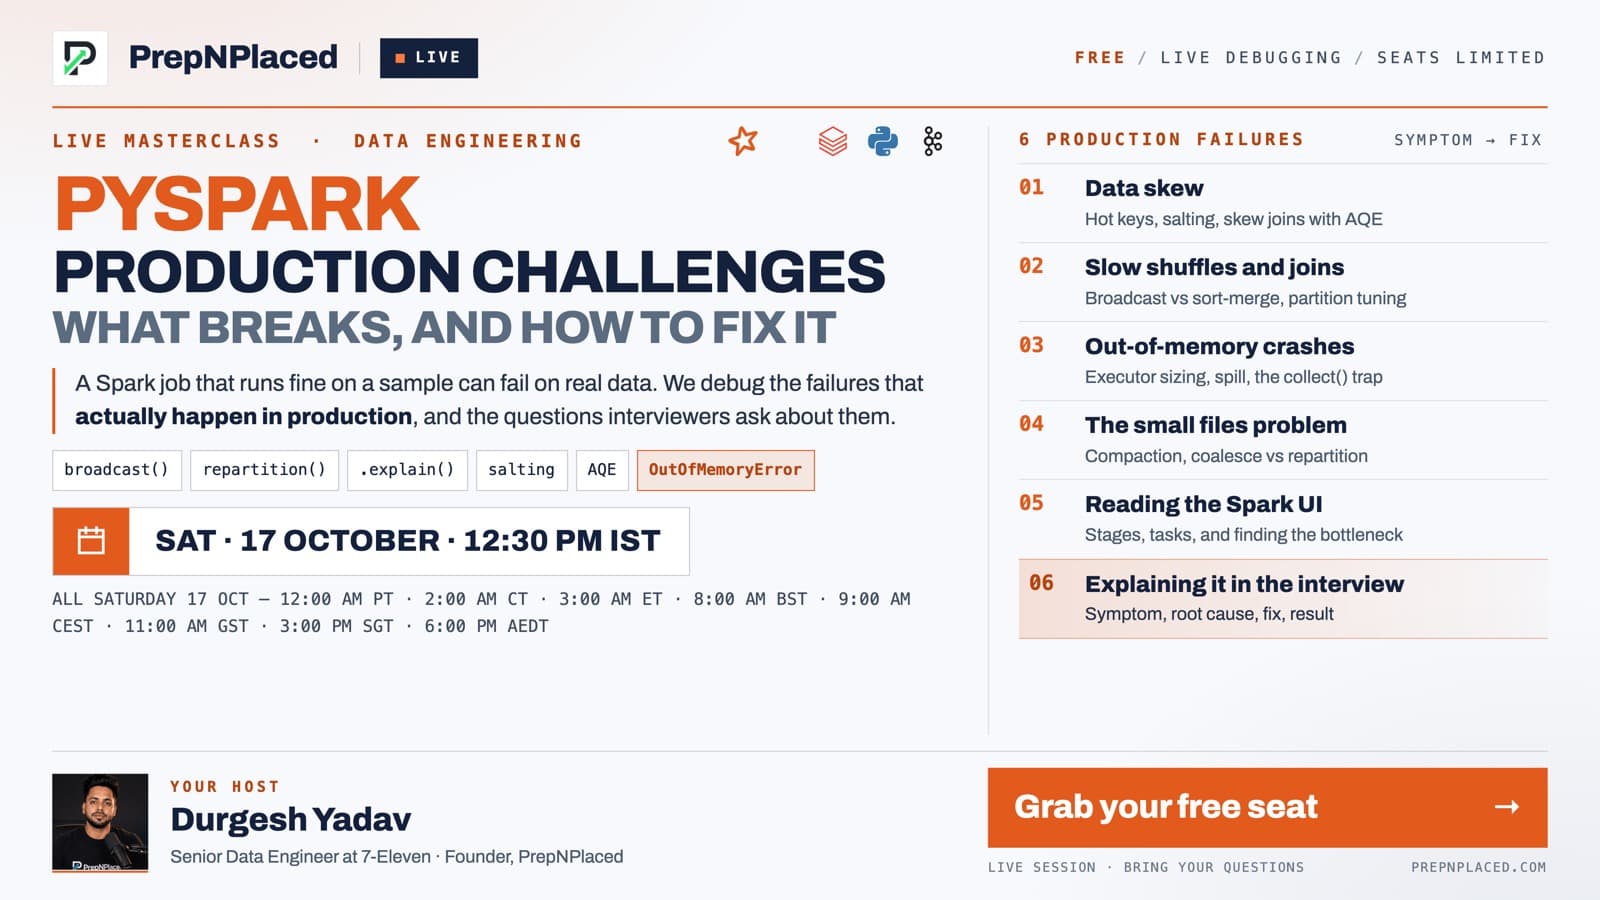
Real PySpark in Production for Real Interviews
Recorded live on Saturday 17 October 2026. A whiteboard class on what Spark does with your job on production data. It starts from a daily sales report that runs in 20 seconds on a sample, then hits an out of memory error in production and takes 2 to 3 hours. Then inside Spark: the driver, the Catalyst optimiser and lazy evaluation, jobs, stages and tasks, how a 100 GB file becomes 800 partitions that 16 cores work through in 50 rounds, how an executor splits its memory, when a shuffle happens, and why collect() can crash the driver. Comes with the 69-page notes, PySpark in Production: the parts nobody teaches, which go further: skew, join plans, spill, small files and the Spark UI.
2 items · Data Engineering · PySpark
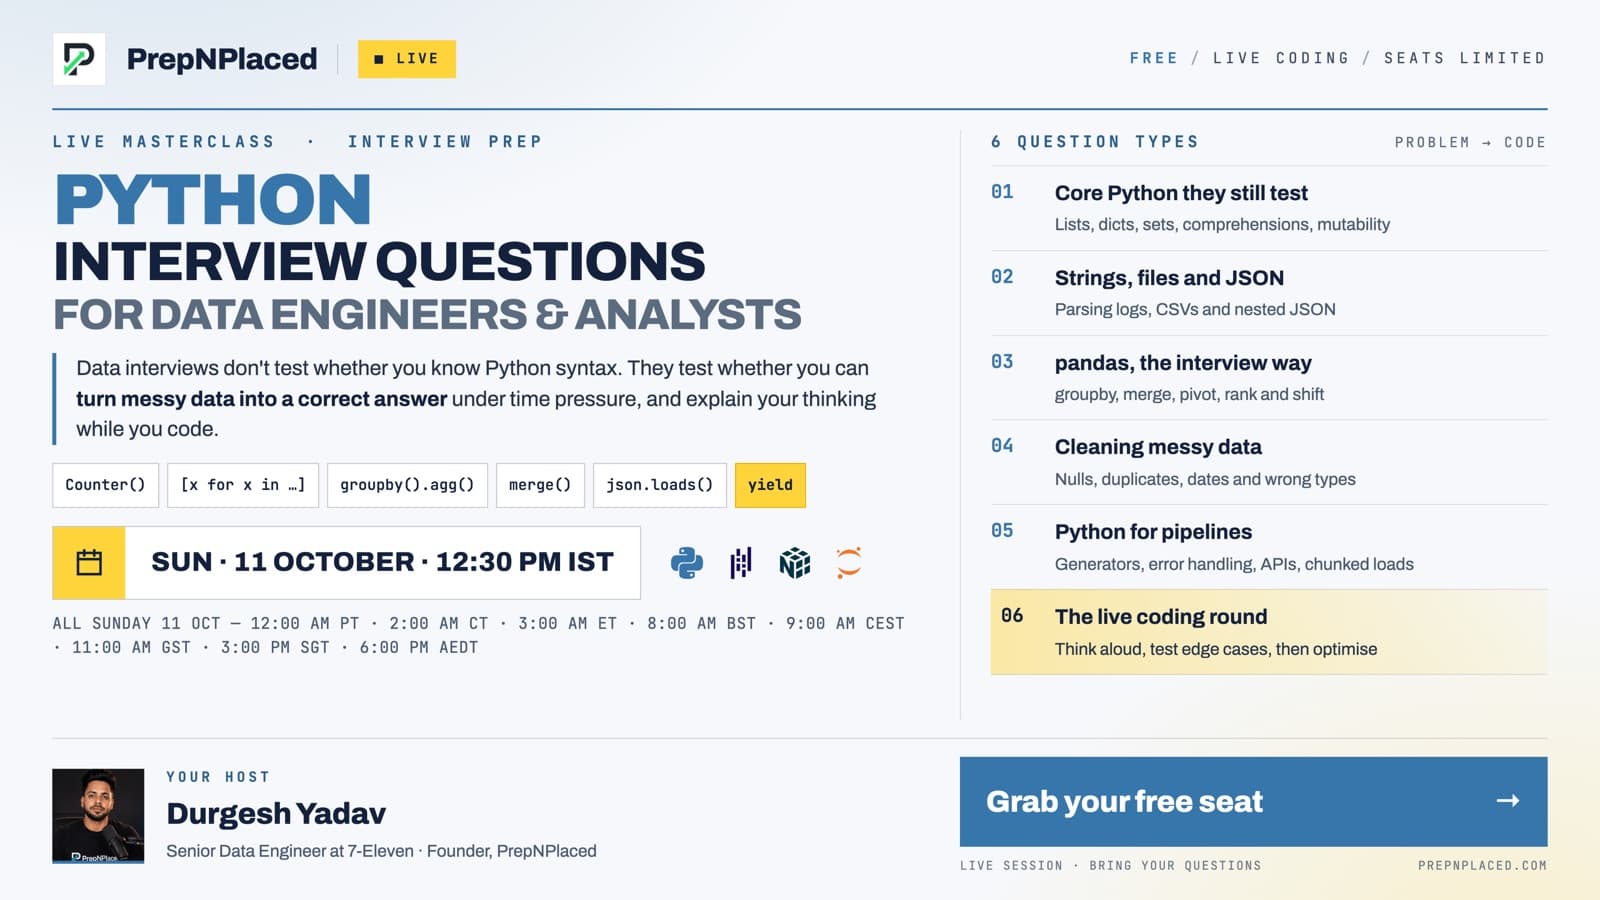
Python Interview Questions for Data Engineers & Analysts
Recorded live on Sunday 11 October 2026. Python problem solving the way a data engineering interview asks it. It opens with why loops, list comprehensions and lambdas still matter in a data job (a pipeline that picks the latest daily sales file out of a folder before PySpark takes over), why interviewers care how many loops your code needs, and where OOP and low-level design fit. Then, live in a Colab notebook: find the duplicate records in a list, first with a nested count and then in one pass with a set, and find the second highest distinct salary, including the cases that break the first attempt: a starting value of None, and a list where every salary is the same.
1 items · Python · Data Interviews
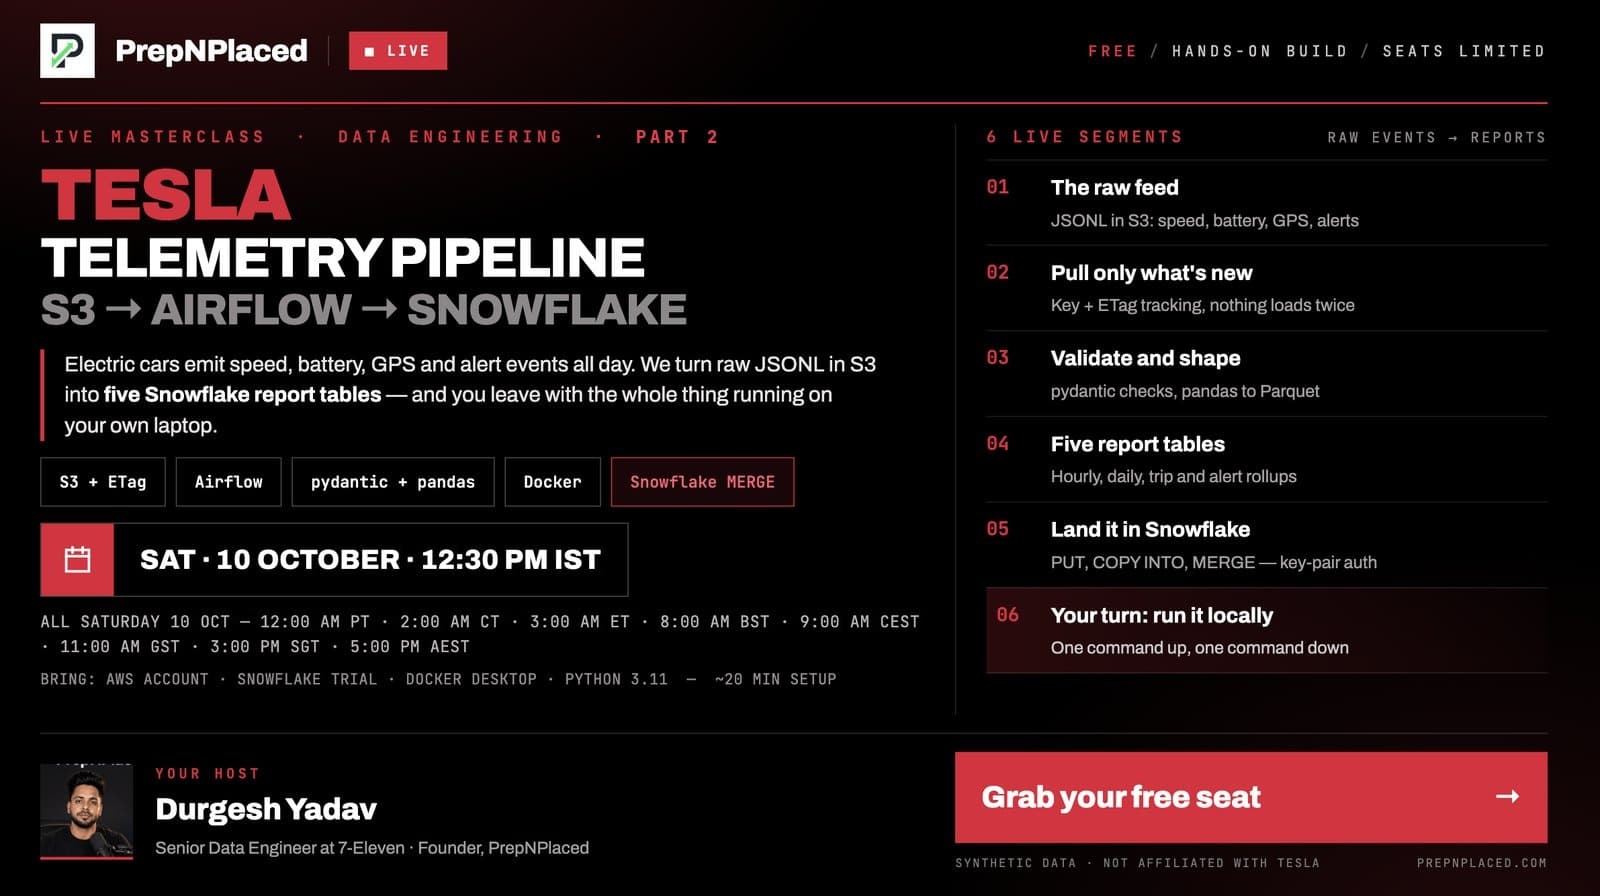
Part 2 - Tesla Telemetry Pipeline
Part 2 of the Tesla Telemetry Pipeline session, recorded live on Saturday 10 October 2026: the explanation half. It reads the project's own walkthrough from start to end: the idea in five sentences, the big picture from the S3 raw zone through the Airflow DAG to Snowflake, what one telemetry event holds, and what every folder and file is for. Then the code, file by file: the DAG and its four tasks, the settings read from the .env file, pulling only the new files from S3, the quality checks, the pandas rollups, the Snowflake database, tables and MERGE procedure, the load through staging tables, and the docker-compose file that runs Airflow. Where private settings were on screen the picture is covered and the audio carries on. Comes with the same public GitHub repo and run guide as Part 1, which was recorded on Saturday 3 October 2026.
3 items · Data Engineering · Hands-On Build
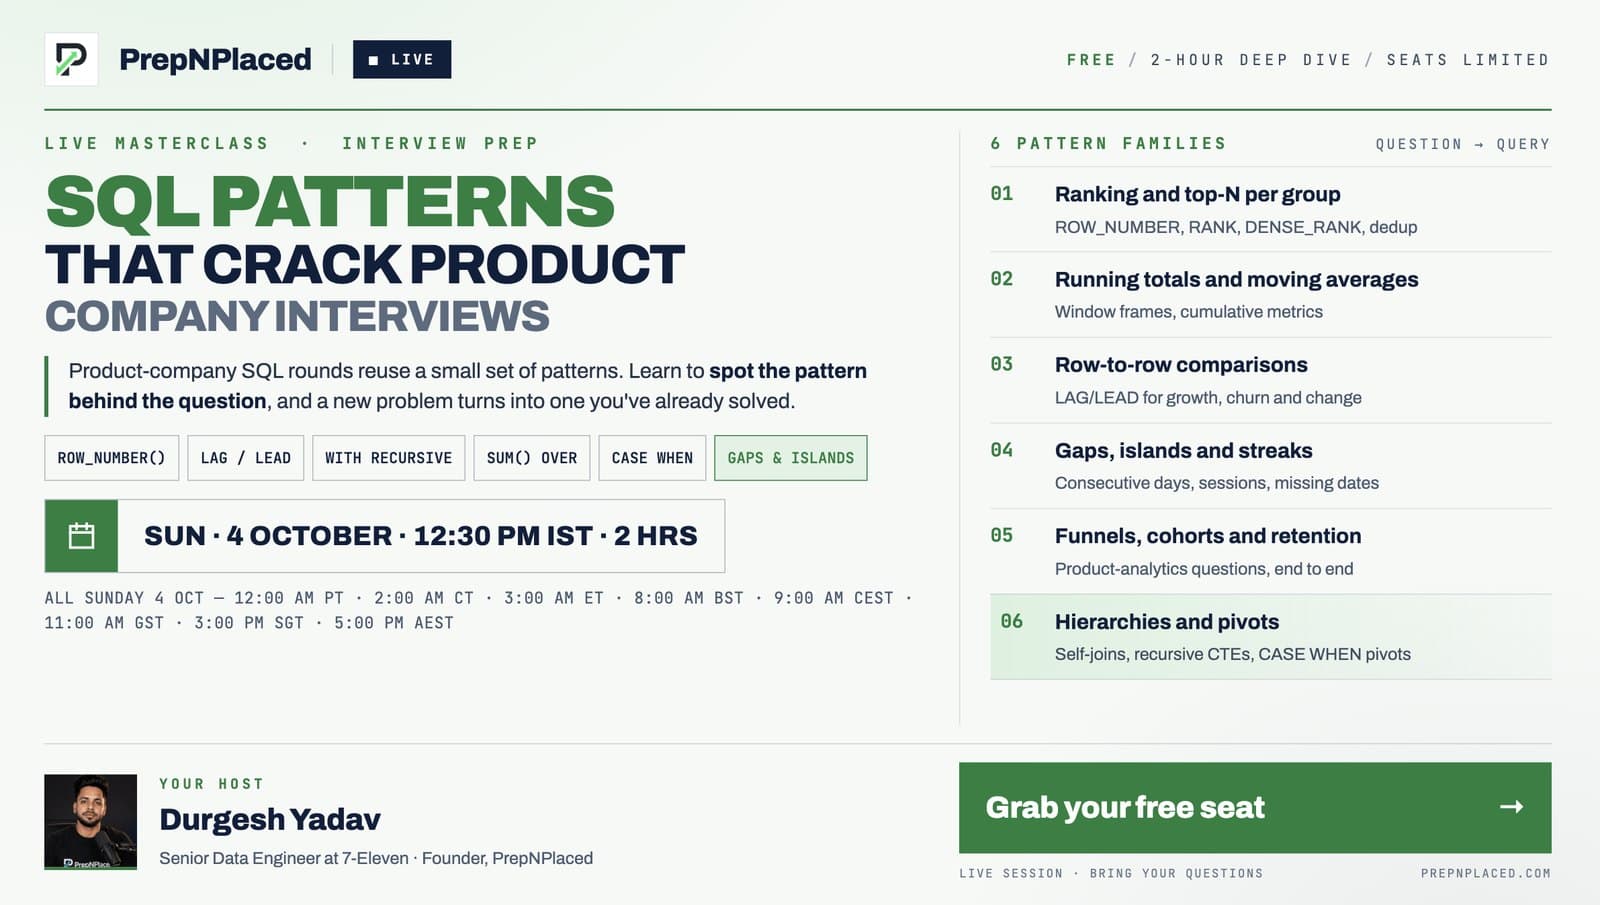
SQL Patterns That Crack Product Company Interviews
Recorded live on Sunday 4 October 2026. The pattern families that keep coming up in product-company SQL rounds: how to recognise each one from the wording of a question, and the query shape that solves it. Comes with the 40-page SQL End to End Notes as a PDF.
2 items · SQL · Product-Company Interviews
Part 1 - Tesla Telemetry Analysis
Part 1 of the Tesla Telemetry Pipeline session, recorded live on Saturday 3 October 2026. It walks through the project in plain words, then sets it up from scratch on a Windows laptop: the S3 bucket and the sample file, an AWS access key, a Snowflake trial and its account details, the .env file, and installing Docker Desktop with WSL 2. Where keys were on screen the picture is covered and the audio carries on. Comes with the public GitHub repo and a run guide that takes you from git clone to five report tables in Snowflake on your own laptop in about 2 hours. Part 2, the explanation, is a separate live session on Saturday 10 October 2026 at 12:30 PM IST.
3 items · Data Engineering · Hands-On Build
Data Engineer 2027: The Real Stack
The 27 September session on the stack that actually gets data engineers hired in 2027, and the order to learn it in, so you stop collecting tutorials and start building toward a job. Comes with the Modern Data Engineering Roadmap 2026-2027: 20 stages from SQL to system design, 89 topics each with a practice task, a checkpoint after every stage, 6 portfolio projects for your GitHub, and the interview rounds decoded at the end. About 57 weeks at 12-15 hours a week.
2 items · Data Engineering · Career Roadmap
Netflix System Design for Data Engineers
The full 20 September session. Most people learn system design as a list of tool names and twenty names in one sitting blur together. This gives you somewhere to hang them: four questions every big system answers, answered live for Netflix — the two clouds, a movie's journey to roughly 1,200 output files, your click's journey across 2,200+ device types, EVCache, MySQL and Cassandra, and the Kafka event pipeline that watches it all. The last segment is yours: Flipkart's MVP designed on the board, scope to failure modes, the way an interviewer makes you. Comes with the instructor's System Design document.
3 items · System Design · Data Engineering Interviews
Your Non-Tech Experience Isn't a Gap
The full 19 September session in two parts, for people who already work. Only 8% of analyst postings are entry-level and 3% for data engineering, so applying to the entry-level door is the wrong move; 26% of DE ads never mention education at all, so the degree is rarely the blocker. What does move is three real projects with a published dashboard and a short write-up. Two hours turning the reporting, stakeholders and business context you already handle into exactly that, plus resume rewrites live on real profiles from the room.
2 items · Career Switch · Data Analyst & Data Engineer
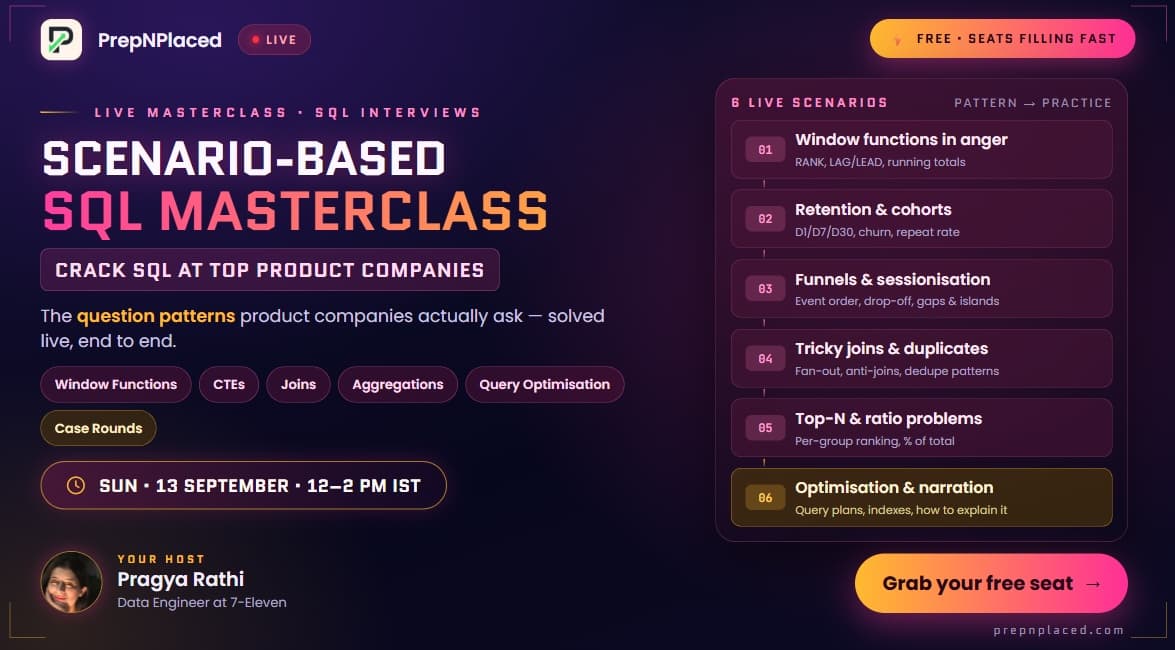
Scenario-Based SQL Masterclass
The full 13 September session. Product-company SQL rounds are not a hundred random questions — they are built on a handful of patterns, and once you see the pattern in the first thirty seconds the query writes itself. Two hours, six live scenarios: window functions in anger (RANK, LAG/LEAD, running totals), retention and cohorts (D1/D7/D30, churn, repeat rate), funnels and sessionisation (event order, drop-off, gaps and islands), tricky joins and duplicates (fan-out, anti-joins, dedupe), top-N and ratio problems (per-group ranking, % of total), then optimisation and narration — query plans, indexes, and how to explain your answer the way interviewers actually score it. Ends with live Q&A on SQL rounds and case interviews.
1 items · SQL · Product-Company Interviews
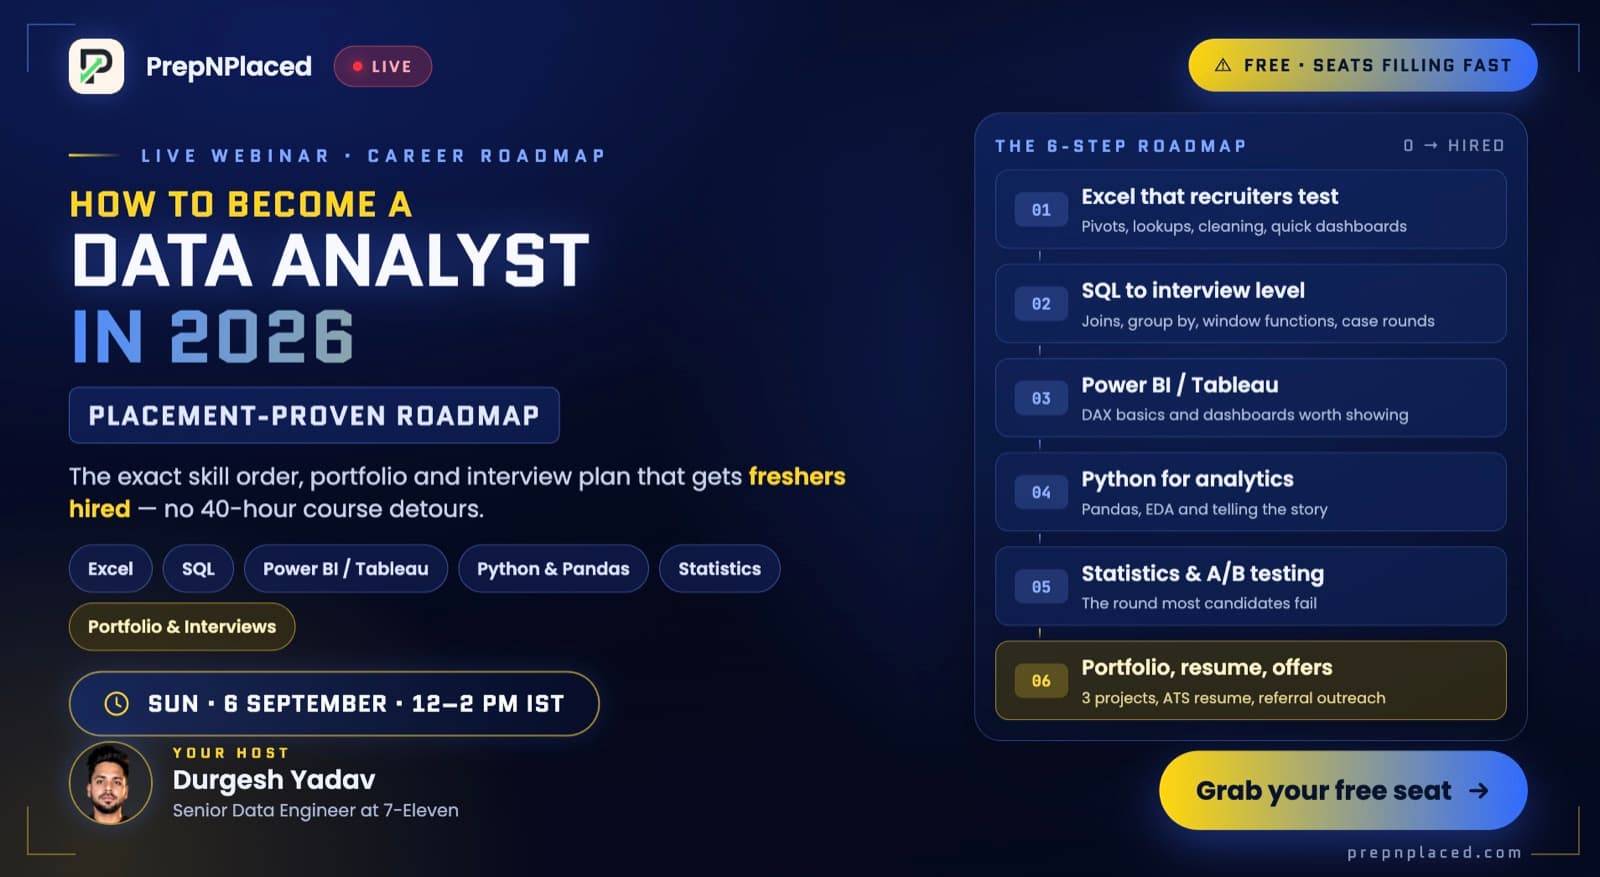
How to Become a Data Analyst in 2026
The full 6 September session — the exact skill order that converts to offers: the Excel recruiters actually test, SQL to interview level, statistics and the A/B round most candidates fail, pandas for real analysis, a dashboard worth showing, then the portfolio, resume and referral plan that closes it. Comes with the 20-page Data Analytics Roadmap 2026: six phases across 24 weeks, each ending in an exit test, plus 8 worked SQL problems, the 7 A/B traps and 30 rapid-fire interview answers.
2 items · Data Analytics · Career Roadmap
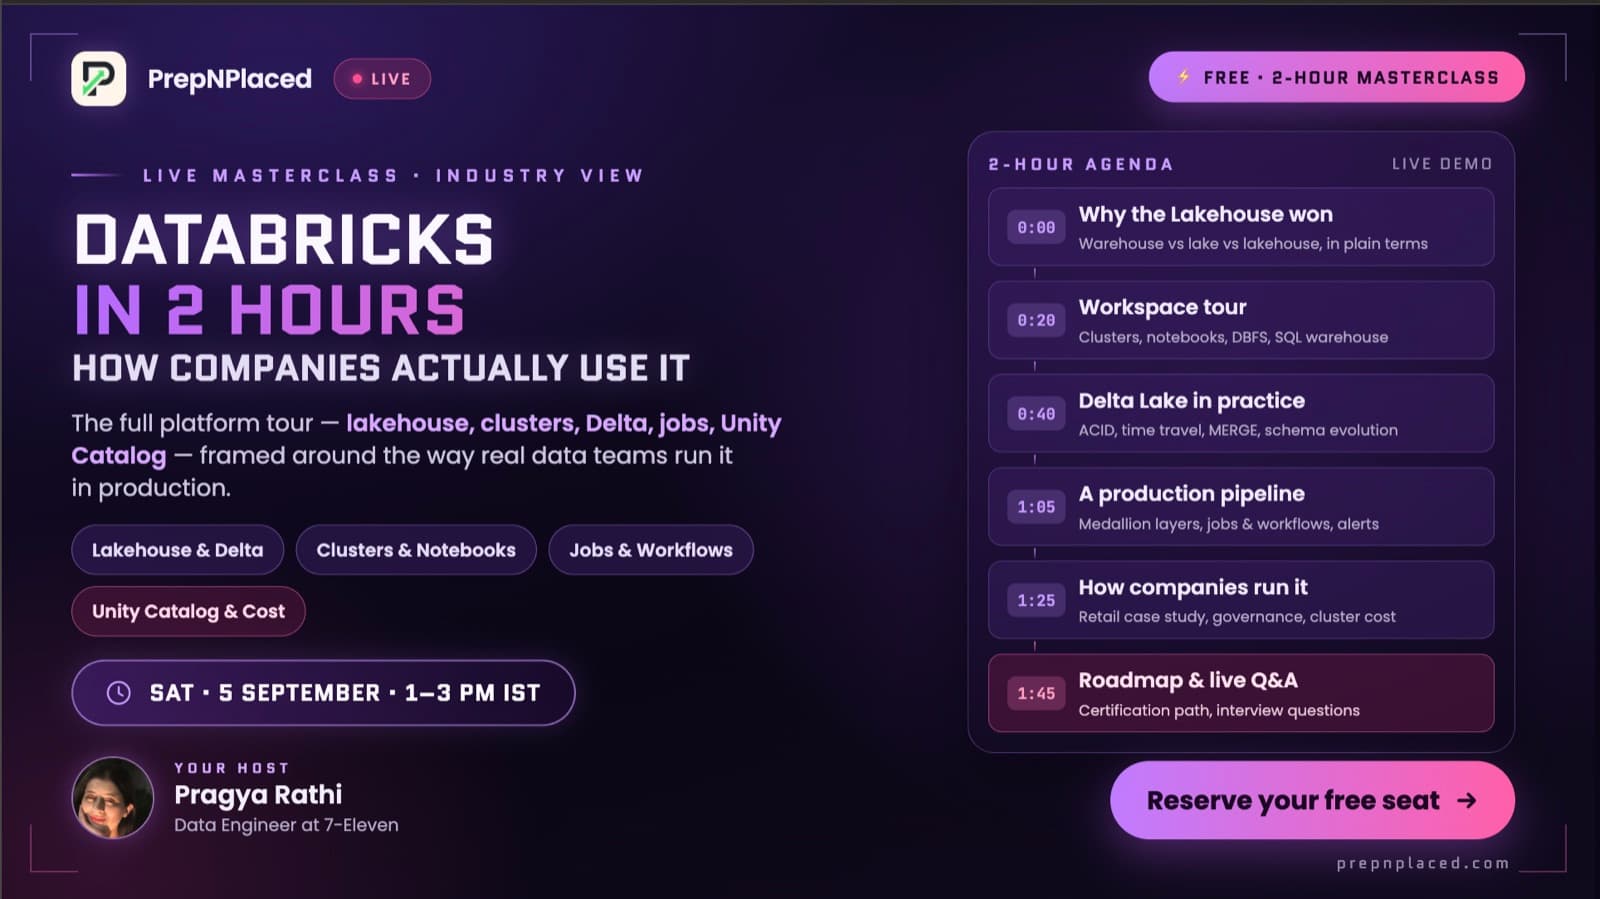
Databricks in 2 Hours — How Companies Actually Use It
The full 5 September session — why teams outgrow Excel and SQL Server, data lake vs warehouse vs lakehouse, the workspace (notebooks, compute, Spark), CSV vs JSON vs Parquet vs Delta, medallion Bronze → Silver → Gold and jobs & workflows — then the hands-on project on a sales dataset. Comes with the 15-page session notes, the class CSV and an importable Bronze → Silver → Gold notebook.
4 items · Data Engineering · Databricks
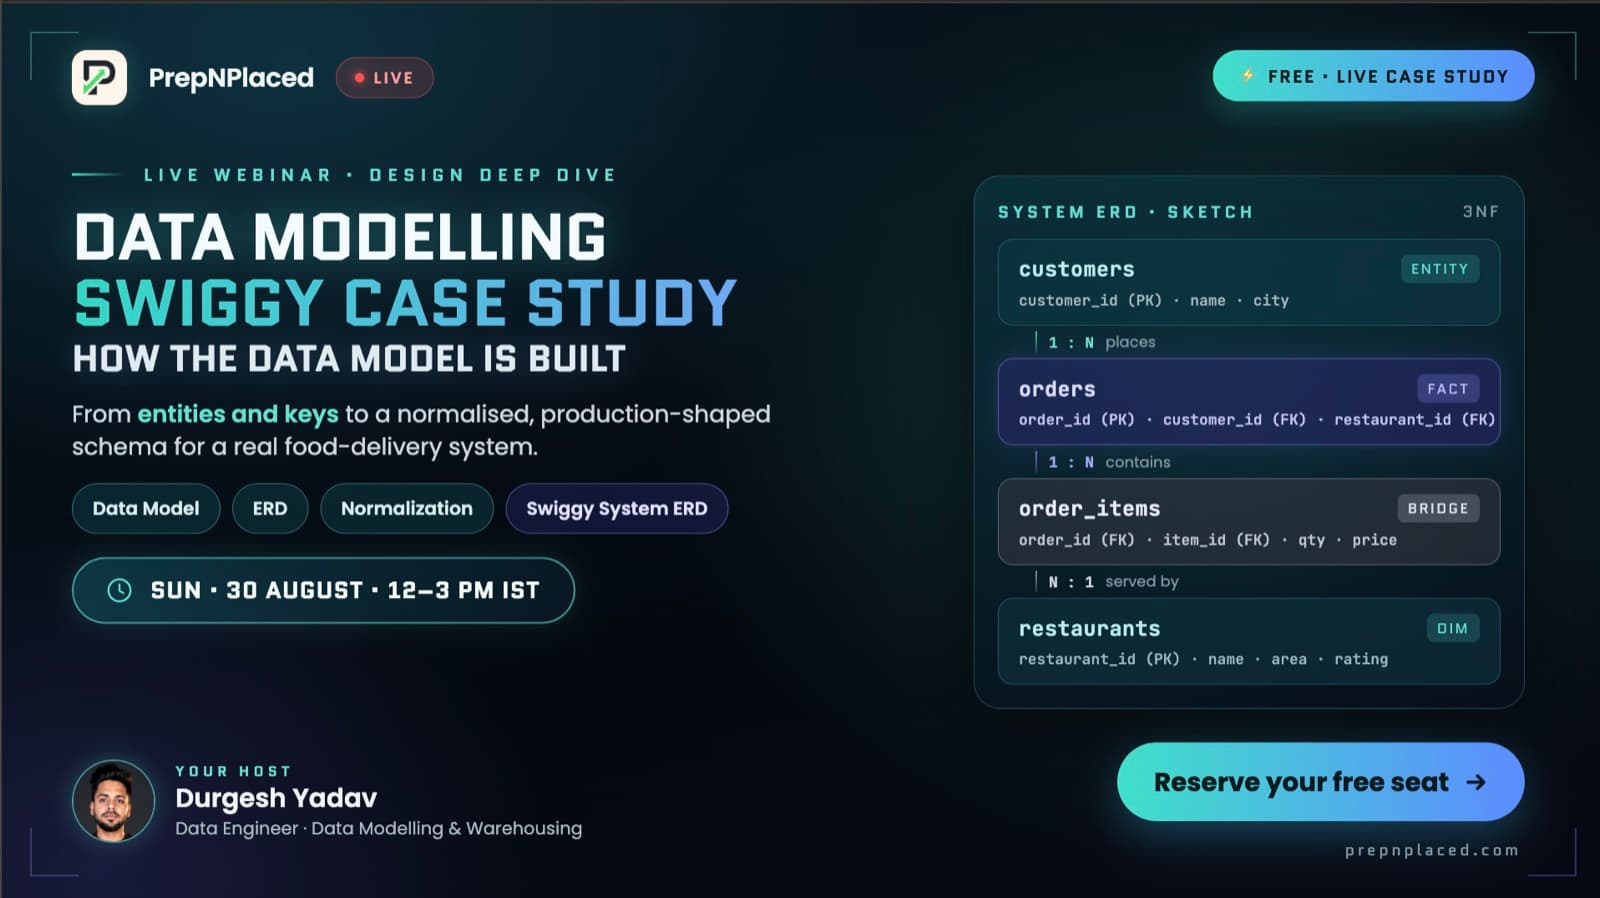
Data Modelling Basics
The full Data Modelling session — entities, keys, cardinality and normalization built into Swiggy's schema live — with the 20-page ER Model & ER Diagrams notes: every symbol, strong vs weak entities, ISA, aggregation, and five real company ERDs worked end to end.
2 items · Data Engineering · Data Modelling
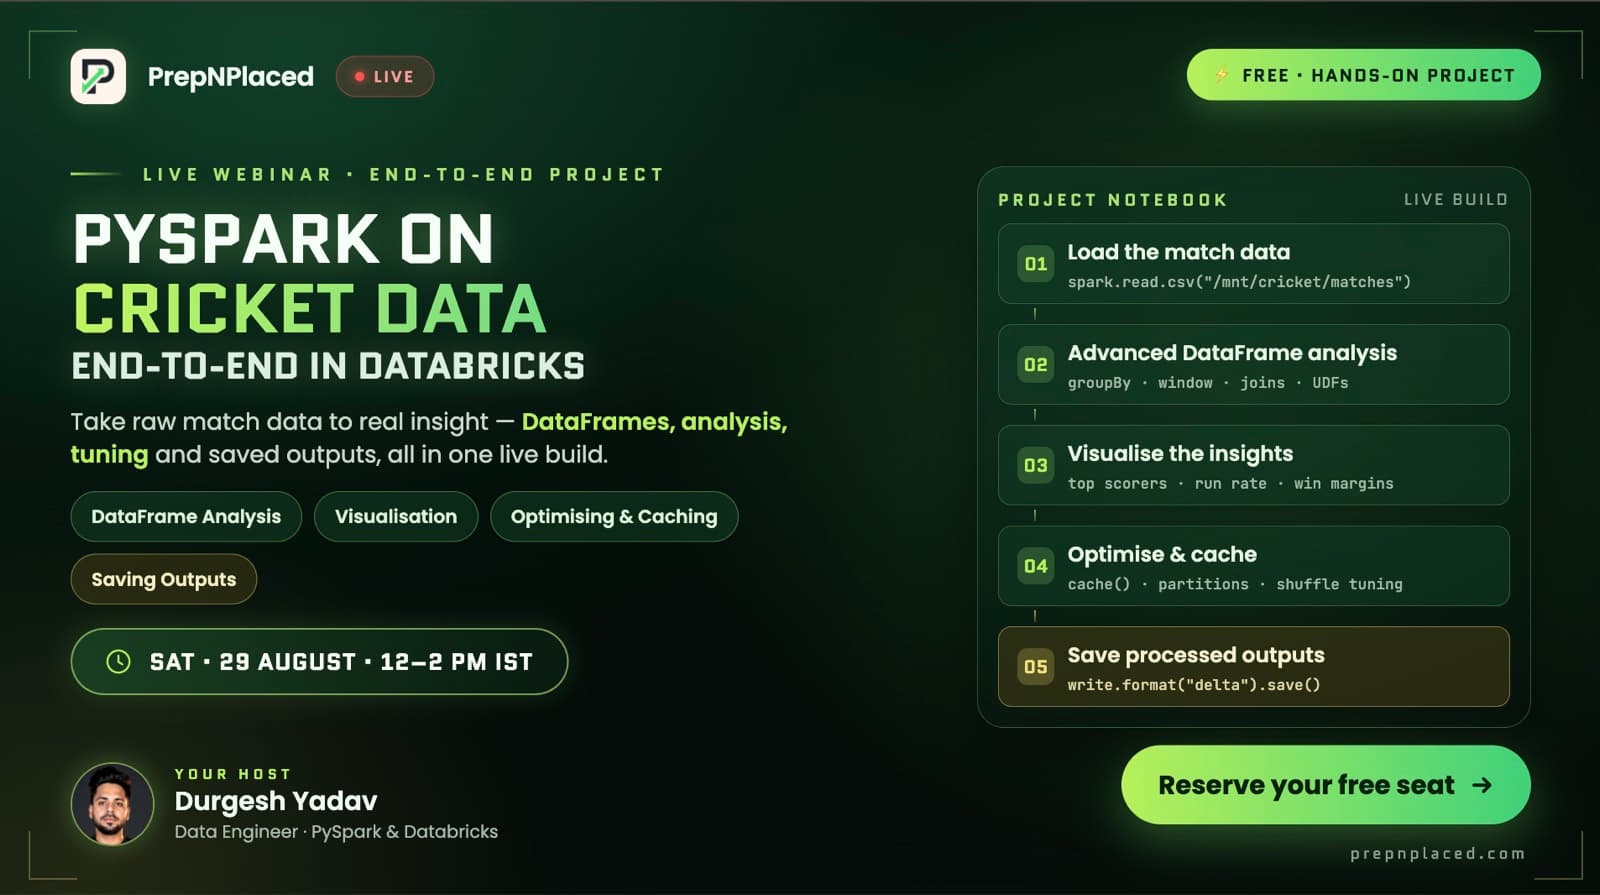
Databricks IPL Project — Medallion Architecture End-to-End
The complete IPL build from the 29 August session: raw ball-by-ball cricket data landing in Databricks, modelled Bronze → Silver → Gold through a modular PySpark pipeline you can run yourself. Comes with the class dataset, the four notebooks that build each layer, and the full written notes — plus the three Databricks sessions a beginner needs first.
7 items · Data Engineering · Databricks
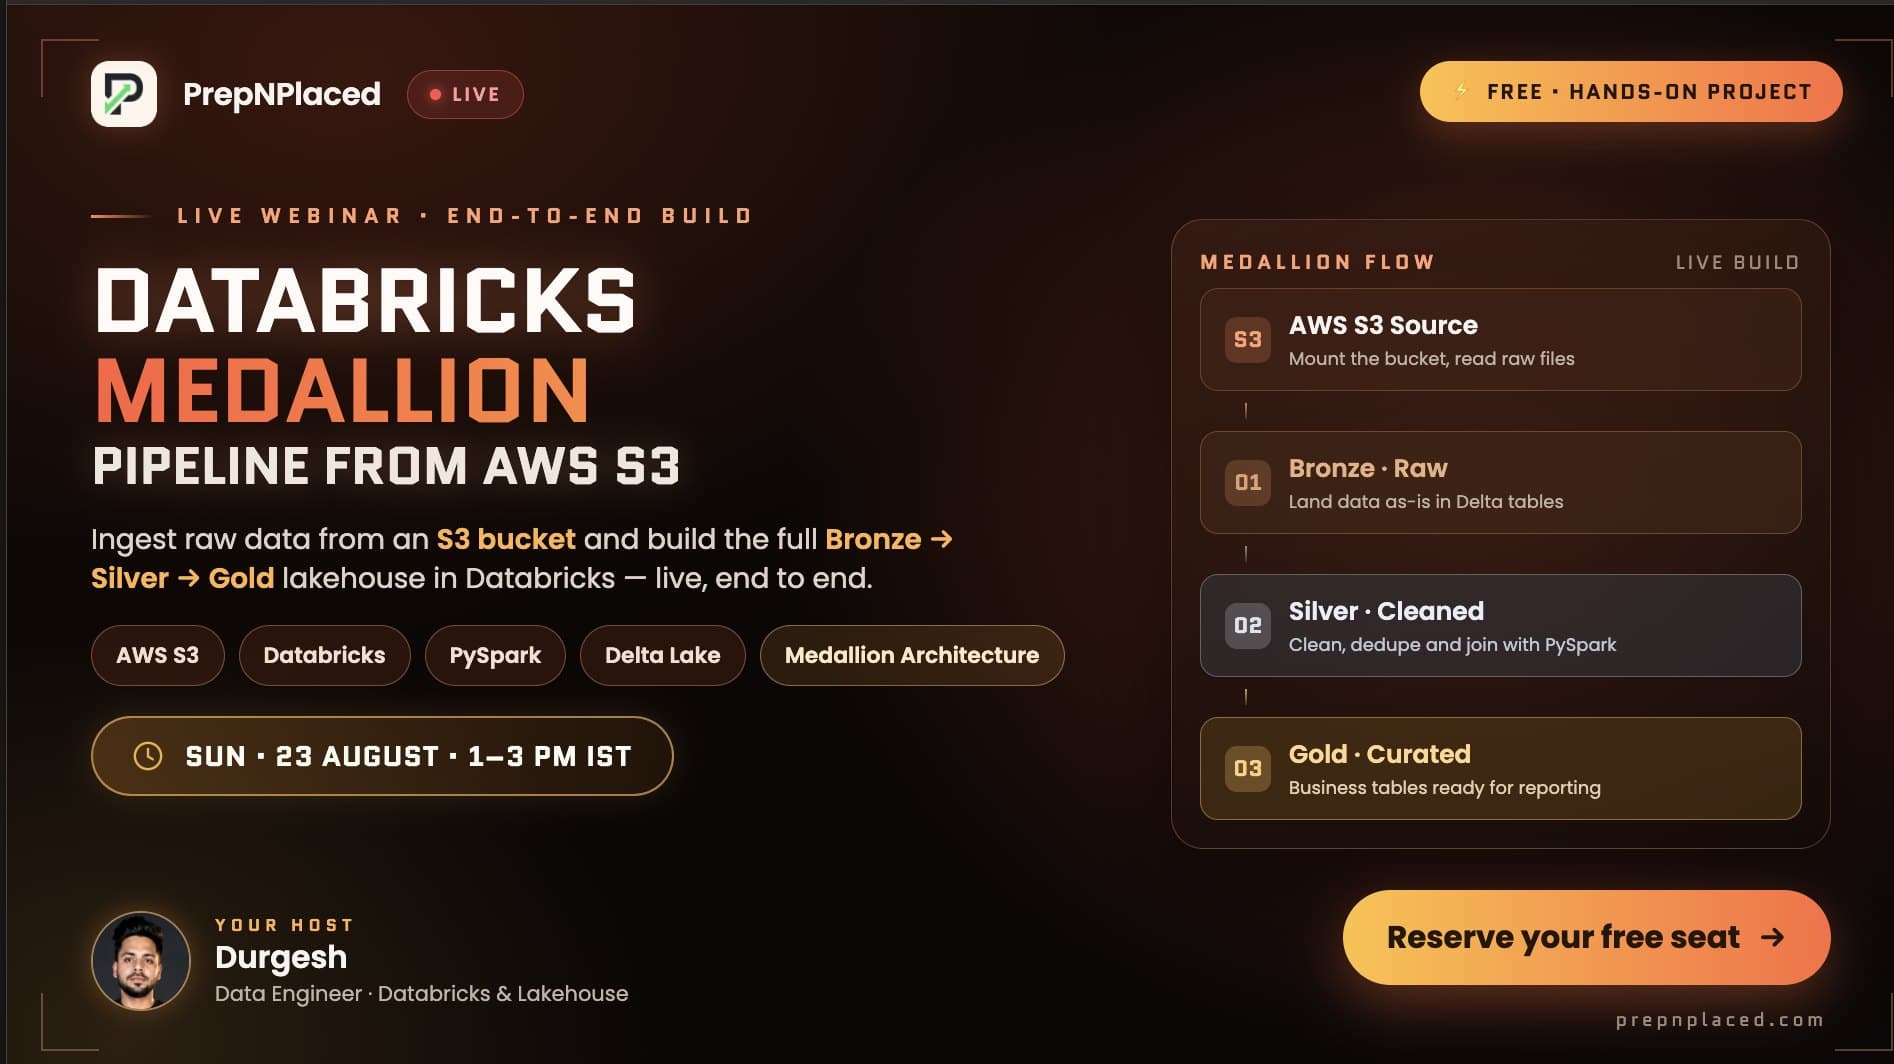
Databricks Medallion Architecture — Payment Reconciliation Project
The full medallion build from the 23 August session: raw vendor payout and store POS files landing in AWS S3, modelled Bronze → Silver → Gold on Databricks into a payment reconciliation you can demo. Comes with the complete project bundle — notebooks, datasets, SQL, workflow config and a step-by-step beginner guide — plus the four prerequisite sessions.
6 items · Data Engineering · Databricks
SQL Interview Questions — 5 Lectures
Five sessions of SQL interview questions worked end to end — read the question, write the query, then talk through why it is the right shape. Watch in order.
5 items · SQL
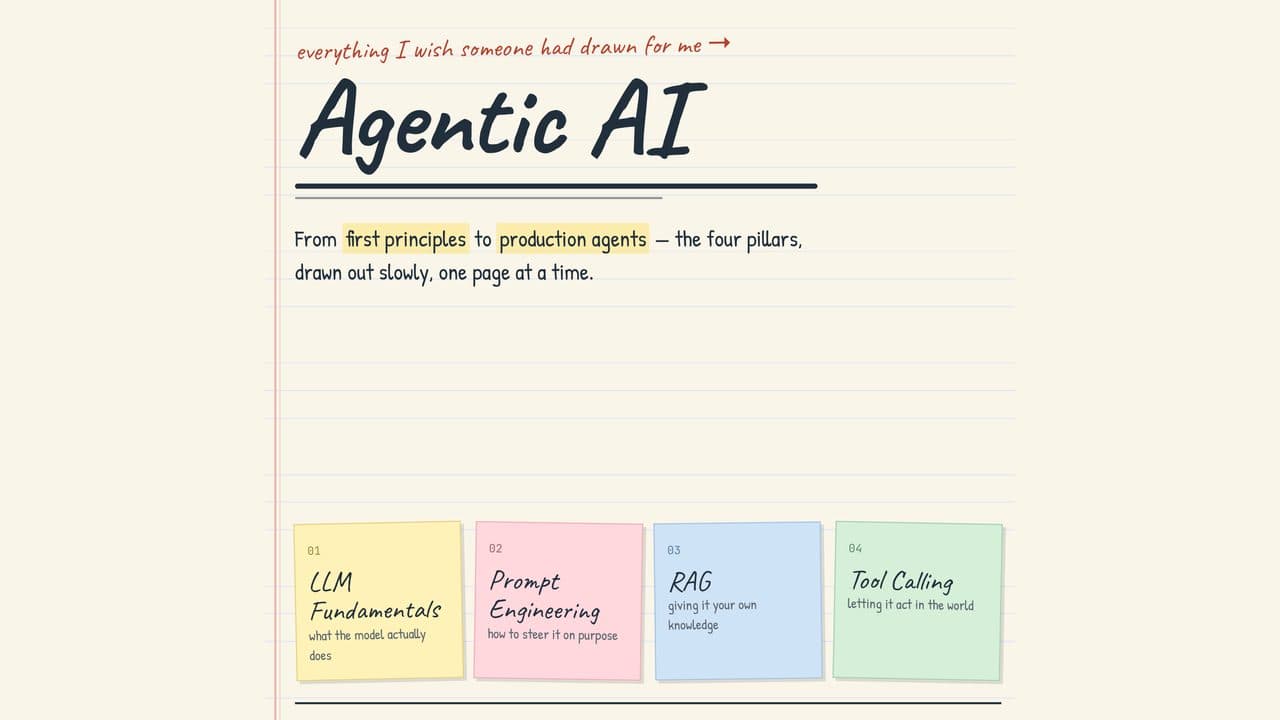
LLMs & Agentic AI for Data Engineering
The full session on LLMs and agentic AI in data engineering workflows, with the hand-drawn 25-page field notebook that goes with it — the four pillars: LLM fundamentals, prompt engineering, RAG and tool calling.
2 items · AI · Data Engineering
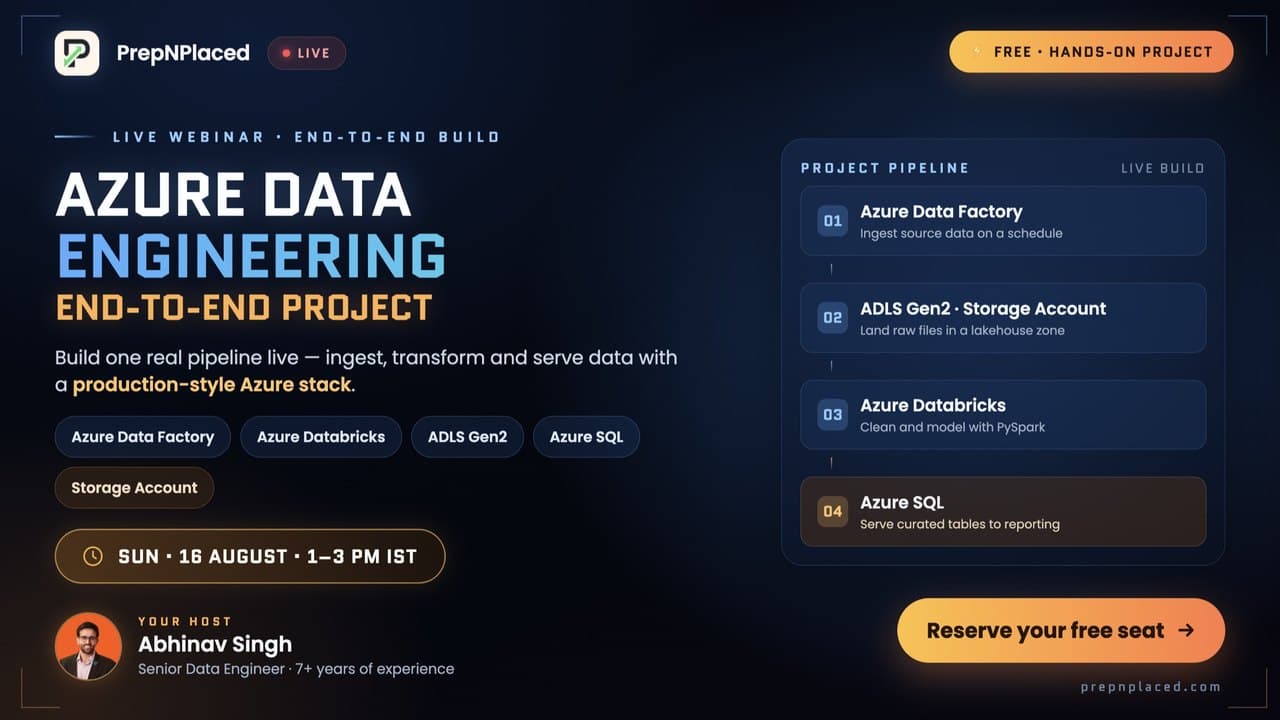
Azure Data Engineering — End-to-End Project
The complete build with Abhinav Singh: Azure SQL through a metadata-driven Data Factory loop into ADLS Gen2, then Databricks modelling it Bronze → Silver → Gold in Unity Catalog. Comes with the project files, the architecture, the prerequisites and a practice brief.
5 items · Data Engineering · Azure
Complete PySpark Module
Five full lectures from zero to a real PySpark project — plus the project notebook, and the optimisation and joining guides as PDFs.
9 items · Data Engineering · Big Data & Spark
Complete Databricks Module
Three end-to-end Databricks sessions — the platform, the lakehouse workflow, and building on it like a data engineer.
3 items · Data Engineering · Databricks
Complete AWS Cloud Module
Five sessions from what the cloud actually is to the AWS services a data engineer uses every day — IAM, EC2, S3, RDS, Lambda and the CLI.
5 items · Data Engineering · AWS Cloud
This session — ₹99
The full recording and every resource from this session, yours to rewatch whenever you like.
Get this sessionEverything — ₹499
- Every module and recording, this one included
- New sessions added for 6 months, no extra charge
- Whatever lands in your window stays yours
Already paid for this session? It is already yours — open your learning hub with the email you registered with.