Free notes · no sign-up to browse
The notes we actually revise from before interviews.
Spark, SQL, Kafka, Snowflake, Airflow, dbt, warehousing and system design, written as revision notes, not textbooks.
- Read the first 4 pages of any note, no sign-in
- Your first download is free with one Google sign-in
- All 117 notes with the Learn Pass, ₹499 for 6 months
Also included in any paid plan and every cohort seat.
- PDF notes
- 117
- pages of revision
- 2,839
- topics covered
- 21
New · the complete notes · sold separately from the vault
The complete notes, in one book
Twenty-eight chapters, Hadoop to Terraform, in one 157-page PDF. Sold on its own: the vault and the Learn Pass do not include it.
Data Engineering End to End Notes
What the 28 chapters give you:
- 28 chapters with commands, configs and interview questions
- Free for Data Engineering cohort learners and mentorship members
- 20 pages free to read after a Google sign-in
₹499 · PDF · 20 pages free to read
New · data modelling from zero to hero · sold separately from the vault
Data modelling, from a paper register to sharded systems
Twenty chapters in seven parts, ER diagrams to replication, then six case studies, in one 93-page PDF. Sold on its own: the vault and the Learn Pass do not include it.
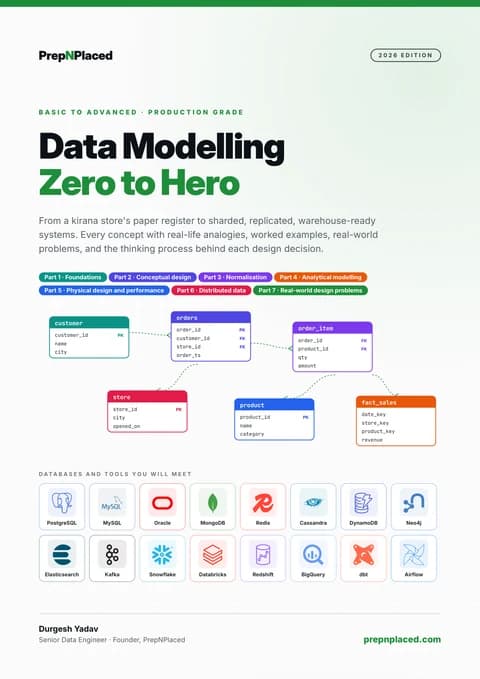
Data Modelling: Zero to Hero
What the 20 chapters give you:
- 20 chapters with worked examples, 6 case studies and interview questions
- Free for Data Engineering cohort learners and mentorship members
- 20 pages free to read after a Google sign-in
₹299 · PDF · 20 pages free to read
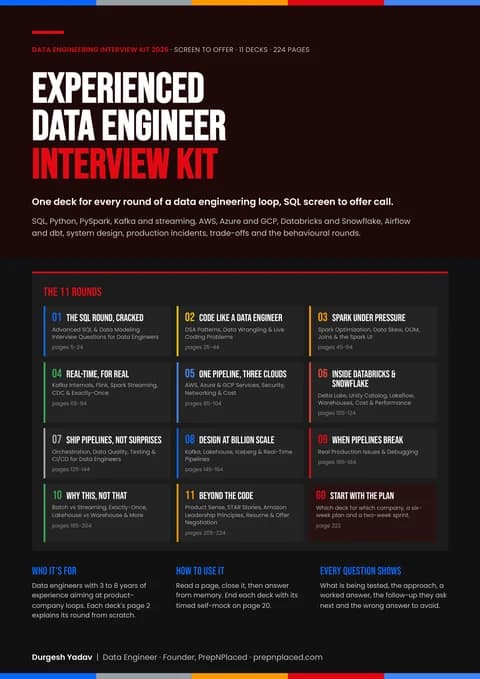
Just launched · sold separately from the vault
Experienced Data Engineering Interview Kit 2026
The 11 decks:
- 01 SQL and modeling
- 02 Python coding
- 03 PySpark
- 04 Kafka and streaming
- 05 AWS, Azure and GCP
- 06 Databricks and Snowflake
- 07 Airflow, dbt and DataOps
- 08 System design
- 09 Scenario questions
- 10 Trade-offs
- 11 Behavioural and offer
₹499 · PDF · 20 pages free to read
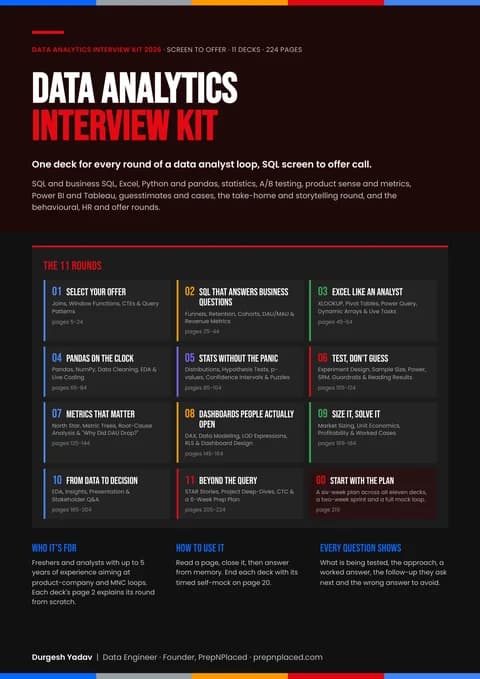
New · for data analyst interviews · sold separately from the vault
Data Analytics Interview Kit 2026
The 11 decks:
- 01 SQL
- 02 Business SQL
- 03 Excel
- 04 Python and pandas
- 05 Statistics
- 06 A/B testing
- 07 Product sense
- 08 Power BI and Tableau
- 09 Cases and guesstimates
- 10 Take-home and storytelling
- 11 Behavioural and offer
₹499 · PDF · 20 pages free to read
New book · sold separately from the vault
Data Engineering System Design: Zero to Hero
- 100 reported questions from 30+ companies, each tagged by evidence
- The PIPELINE method: eight steps for the 45 minutes
- 26 designs worked end to end, 19 cheat sheets and a master checklist
₹499. PDF, 111 pages.
Just added
Latest notes
Just added — newest first.
 NewSQL
100 SQL Interview Questions for Product-Based Companies
100 questions from easy to expert for product-based company interviews, each solved on one store dataset with the PostgreSQL 16 query and its real output.
217 pages3.0 MB
 Big Data
Apache Spark & PySpark — End to End Notes
Spark's engine, execution model and optimiser, then PySpark hands-on from RDDs to streaming. Chapters 6 and 7 of the Data Engineering End to End Notes.
14 pages537 KB
 Streaming
Apache Kafka — End to End Notes
Topics, partitions, brokers, replication, producers, consumers, Schema Registry and real setups. Chapter 10 of the Data Engineering End to End Notes.
7 pages456 KB
 Orchestration
Apache Airflow — End to End Notes
DAGs, operators, XCom, TaskFlow, scheduling, catchup and backfill, connections and alerts. Chapter 11 of the Data Engineering End to End Notes.
7 pages464 KB
The library
117 PDF notes · first download free
- NewSQL
100 SQL Interview Questions for Product-Based Companies
100 questions from easy to expert for product-based company interviews, each solved on one store dataset with the PostgreSQL 16 query and its real output.
217 pages3.0 MB
- Big Data
Apache Spark & PySpark — End to End Notes
Spark's engine, execution model and optimiser, then PySpark hands-on from RDDs to streaming. Chapters 6 and 7 of the Data Engineering End to End Notes.
14 pages537 KB
- Streaming
Apache Kafka — End to End Notes
Topics, partitions, brokers, replication, producers, consumers, Schema Registry and real setups. Chapter 10 of the Data Engineering End to End Notes.
7 pages456 KB
- Orchestration
Apache Airflow — End to End Notes
DAGs, operators, XCom, TaskFlow, scheduling, catchup and backfill, connections and alerts. Chapter 11 of the Data Engineering End to End Notes.
7 pages464 KB
 Cloud
Microsoft Azure — End to End Notes
Identity, compute, storage, networking, databases, DevOps and monitoring on Azure. Chapter 16 of the Data Engineering End to End Notes.
8 pages459 KB
 Cloud
Google Cloud Platform — End to End Notes
IAM, compute, storage, databases, networking, Vertex AI, operations and cost control. Chapter 17 of the Data Engineering End to End Notes.
7 pages449 KB
 Warehouse
Data Warehousing — End to End Notes
OLTP vs OLAP, warehouse architecture, dimensional modelling, lakes and lakehouses, and performance. Chapter 20 of the Data Engineering End to End Notes.
5 pages426 KB
 Big Data
 & Hadoop — End to End Notes
Why one machine stops being enough, Hadoop and HDFS inside out, MapReduce and YARN. Chapters 1 to 3 of the Data Engineering End to End Notes.
16 pages293 KB
 Big Data
Apache Hive — End to End Notes
SQL on big data: architecture, setup, tables, partitions, buckets, functions and joins. Chapter 4 of the Data Engineering End to End Notes.
7 pages203 KB
 Big Data
Apache HBase — End to End Notes
NoSQL on Hadoop: random, real-time reads and writes on top of HDFS. Chapter 5 of the Data Engineering End to End Notes.
6 pages166 KB
 Pipelines
Data Pipelines — End to End Notes
Pipeline anatomy, ETL vs ELT, batch vs real-time, windows and the Lambda architecture. Chapter 8 of the Data Engineering End to End Notes.
6 pages150 KB
 Cloud
Docker & Compose — End to End Notes
Images, containers, Dockerfiles, debugging and multi-container stacks with Compose. Chapter 9 of the Data Engineering End to End Notes.
6 pages164 KB
 Cloud
AWS for Data Engineers — End to End Notes
IAM and EC2, S3 and Route 53, Lambda and VPC, Glue and Athena with the Data Catalog. Chapters 12 to 15 of the Data Engineering End to End Notes.
19 pages307 KB
 Architecture
Distributed Databases & Cassandra — End to End Notes
CAP, consistency, replication vs sharding; Cassandra's masterless design, modelling and CQL. Chapters 18 and 19 of the Data Engineering End to End Notes.
12 pages222 KB
 Warehouse
Amazon Redshift — End to End Notes
MPP columnar warehouse on AWS: architecture, loading, table design, tuning, Spectrum and querying. Chapter 21 of the Data Engineering End to End Notes.
7 pages169 KB
 Warehouse
Google BigQuery — End to End Notes
Serverless warehouse: Dremel, datasets and tables, loading, partitioning, clustering and SQL. Chapter 22 of the Data Engineering End to End Notes.
6 pages163 KB
 Cloud
Kubernetes — End to End Notes
Architecture, GKE, core objects, storage, autoscaling and stateful data workloads. Chapter 23 of the Data Engineering End to End Notes.
7 pages186 KB
 Warehouse
Snowflake — End to End Notes
Architecture, objects and RBAC, Time Travel, warehouses, stages, Snowpipe, Streams and Tasks. Chapter 24 of the Data Engineering End to End Notes.
8 pages195 KB
 GitLab & CI/CD
GitLab CI/CD — End to End Notes
The DevSecOps platform, runners and .gitlab-ci.yml from the first job to scheduled pipelines. Chapter 25 of the Data Engineering End to End Notes.
8 pages190 KB
 Cloud
Terraform — End to End Notes
Infrastructure as Code: core workflow, state, modules, variables, expressions and real AWS builds. Chapter 26 of the Data Engineering End to End Notes.
8 pages193 KB
 Big Data
Databricks SQL & Performance Notes
All 19 topics for making Databricks and Spark queries fast: warehouses and Photon, Query Profile and EXPLAIN, joins, AQE, skew, pruning, stats and caching.
25 pages432 KB
 Architecture
Delta Lake — Complete Notes
The log, ACID and OCC, time travel, VACUUM, OPTIMIZE, ZORDER, liquid clustering, MERGE, CDF and deletion vectors. Every block ran on a real Delta table.
27 pages518 KB
 Analytics
Why Did the Metric Drop? — One Framework, 13 Worked Cases
The 6-step framework interviewers grade, metric trees with worked arithmetic, Simpson's paradox with real numbers, 13 cases from food delivery to UPI.
19 pages1.7 MB
 BI & Viz
Power BI — End to End Project
Raw CSVs to a published, secured report: a real brief with 8 questions, every M and DAX formula written out, an April to March fiscal year, RLS, refresh.
19 pages1.7 MB
 Cloud
Why Your Data Bill Doubled — Cloud Cost Optimisation
How Snowflake, Databricks, BigQuery and AWS actually bill, the queries that find the expensive 10%, hidden network costs, a worked case and FinOps habits.
19 pages1.7 MB
 AI & LLMs
Data Engineering for AI — RAG, Agents & LLM Pipelines
The pipelines behind RAG, agents and LLM apps: parsing, six chunking strategies, versioned embeddings, pgvector hybrid search, fresh indexes, evals, ACLs.
19 pages1.8 MB
 Data Quality
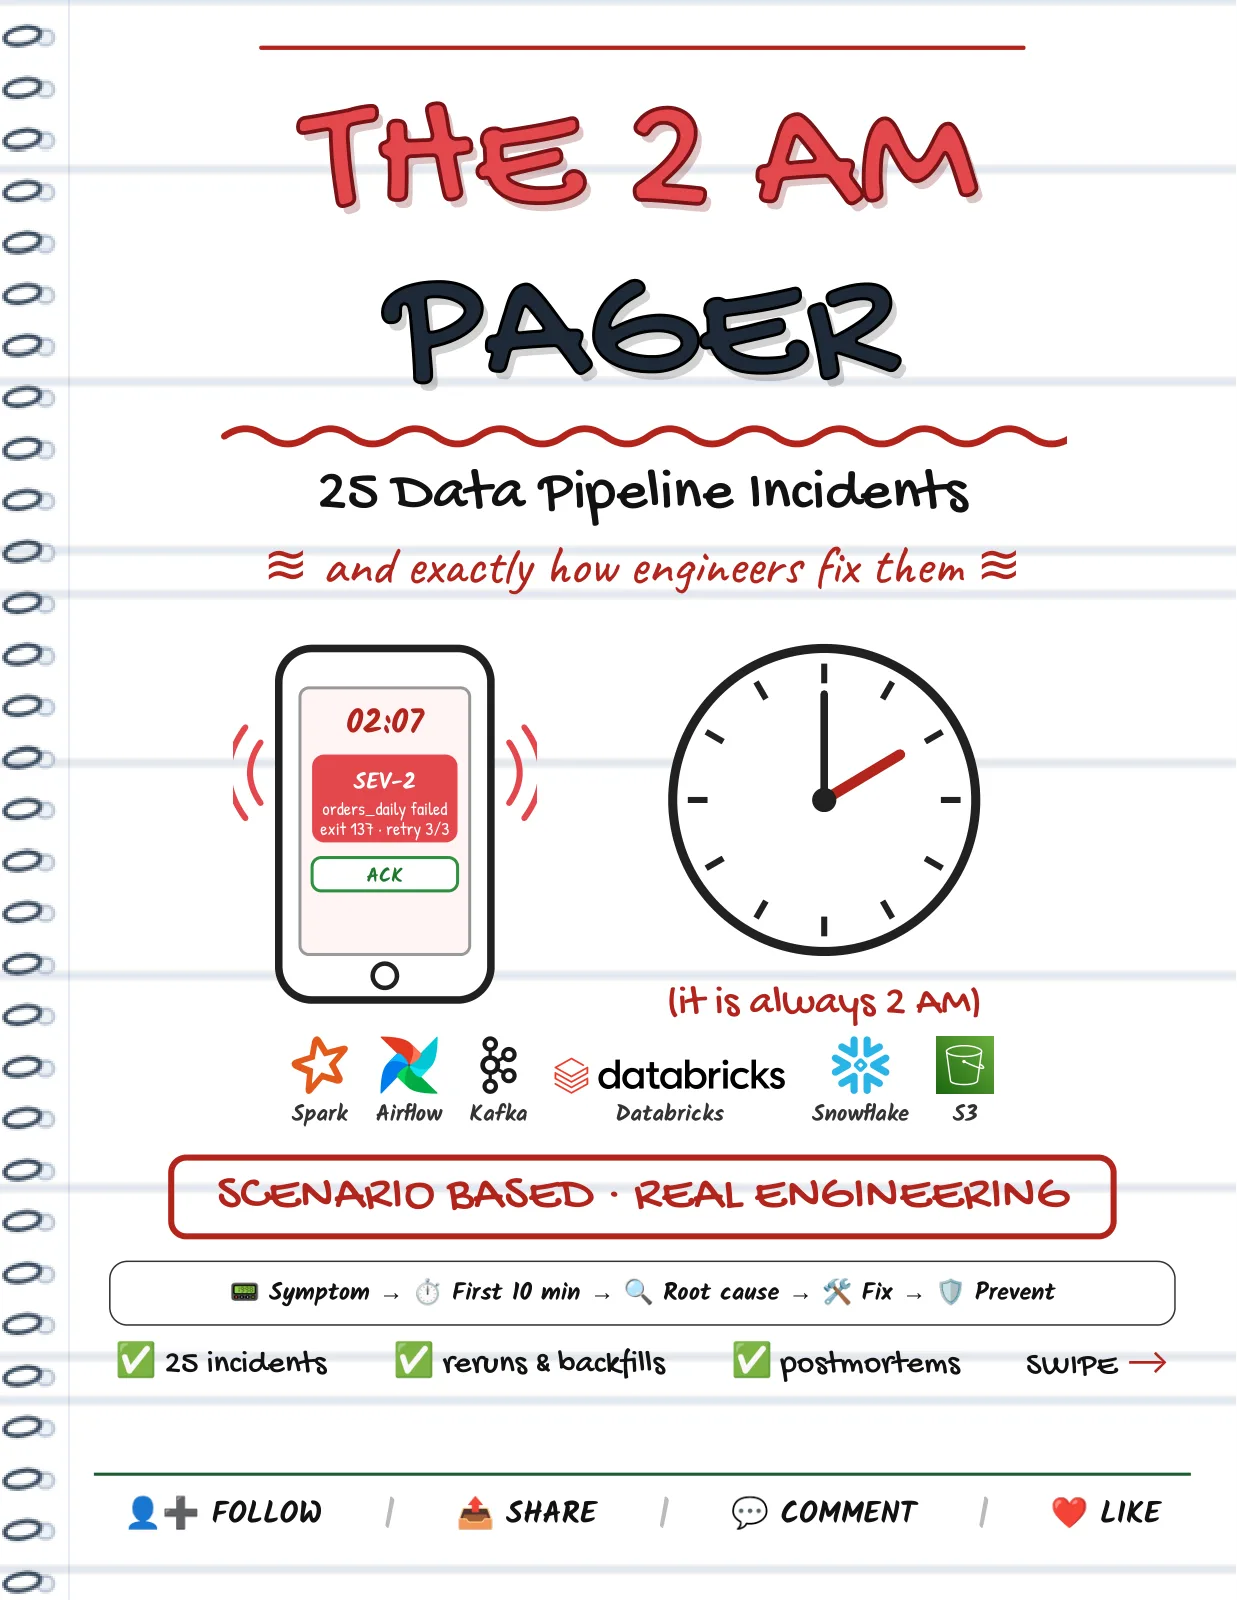
The 2 AM Pager — 25 Data Pipeline Incidents
25 data pipeline incidents on Spark, Airflow, Kafka, CDC, warehouses and S3: symptom, first 10 minutes, root cause, fix, prevention, reruns, postmortems.
19 pages1.8 MB
 Analytics
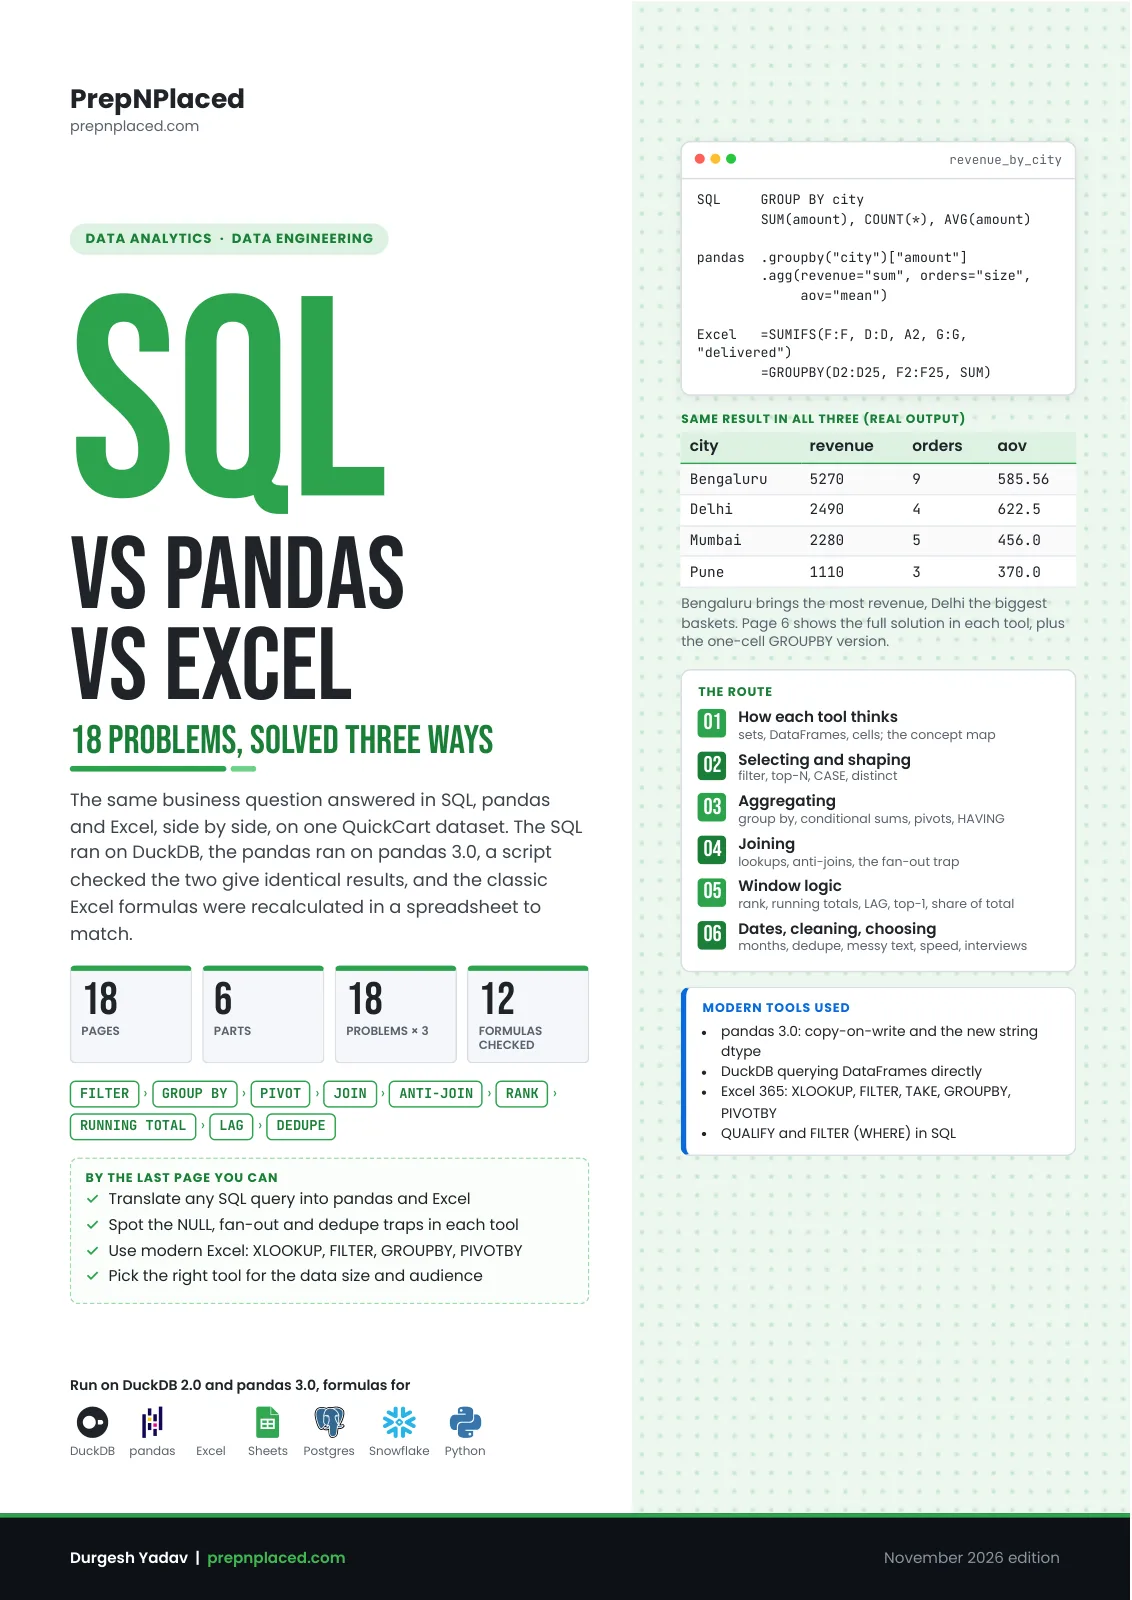
SQL vs Pandas vs Excel — 18 Problems, Solved Three Ways
The same 18 business questions answered in SQL, pandas and Excel side by side on one dataset. SQL ran on DuckDB, pandas on 3.0, and the results match.
18 pages357 KB
 Analytics
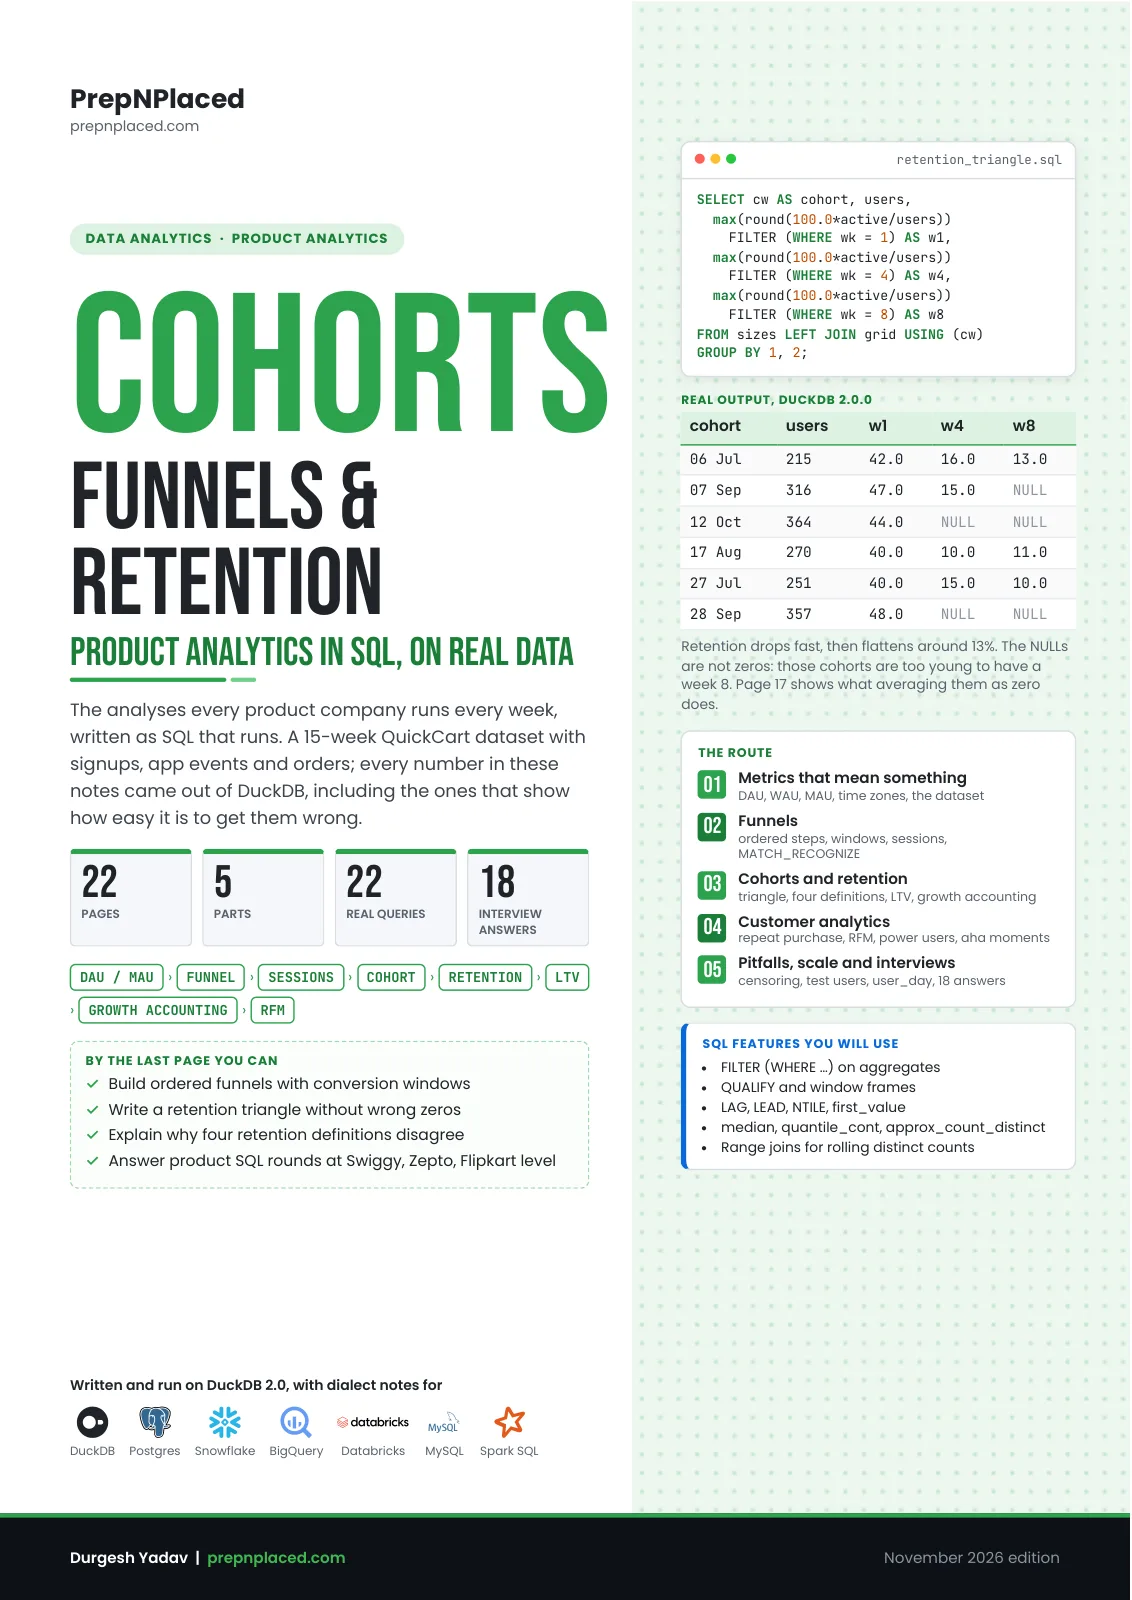
Cohorts, Funnels & Retention — Product Analytics in SQL
DAU/MAU, ordered funnels, sessions, the retention triangle, four retention definitions, LTV, growth accounting and RFM, as SQL that runs on real data.
22 pages396 KB
 Cloud
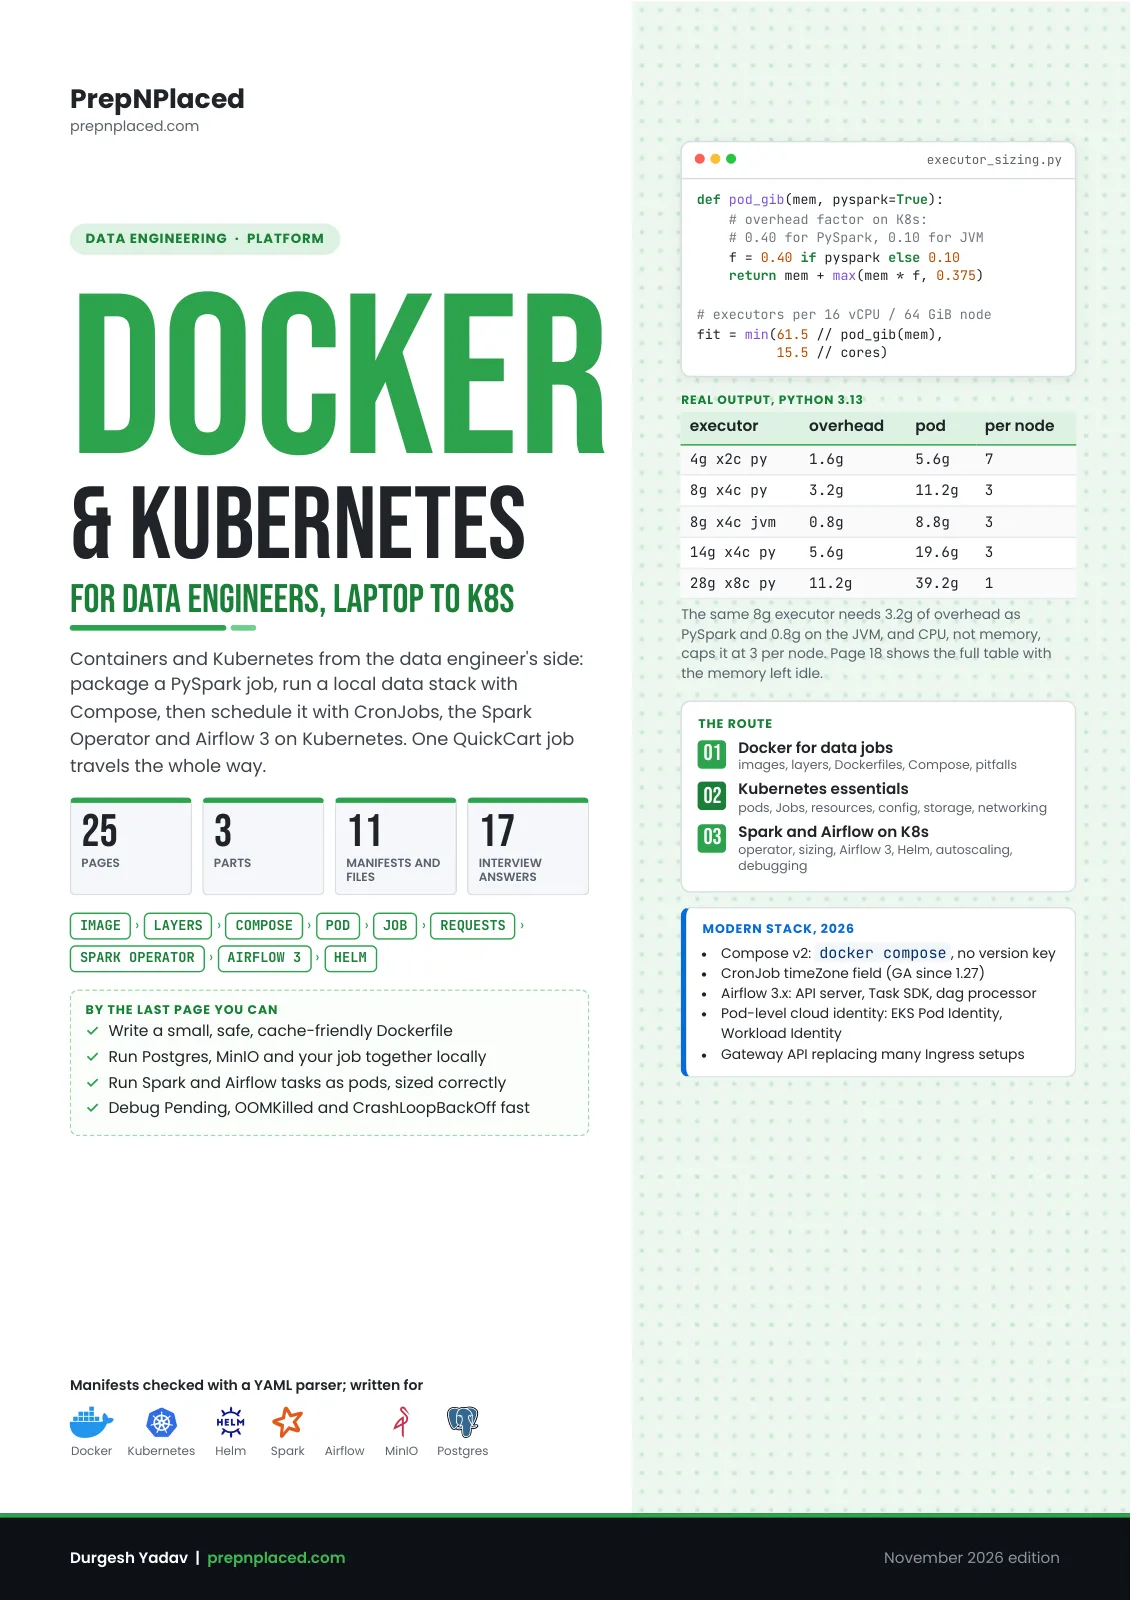
Docker & Kubernetes for Data Engineers
Package a PySpark job, run a local stack with Compose, then schedule it with CronJobs, the Spark Operator and Airflow 3 on Kubernetes, laptop to cluster.
25 pages439 KB
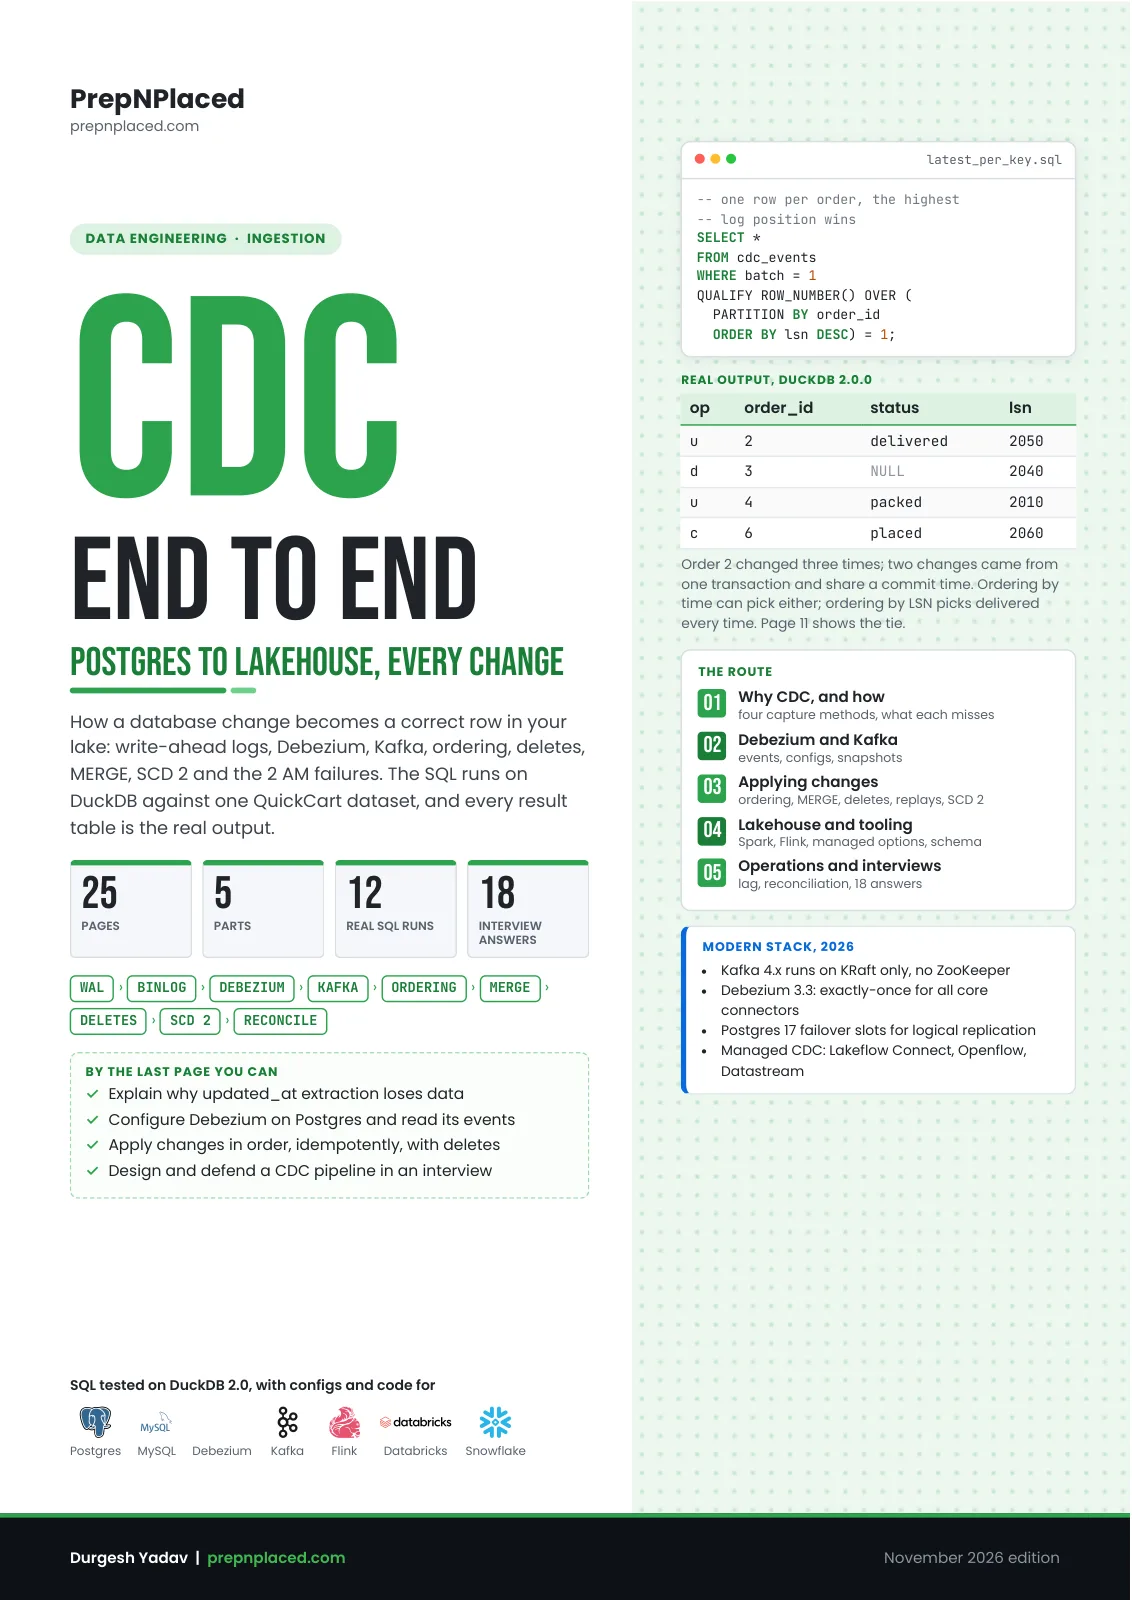 Streaming
CDC — End to End Notes
How a database change becomes a correct row in your lake: write-ahead logs, Debezium, Kafka, ordering, deletes, MERGE, SCD 2 and the 2 AM failures, in SQL.
25 pages455 KB
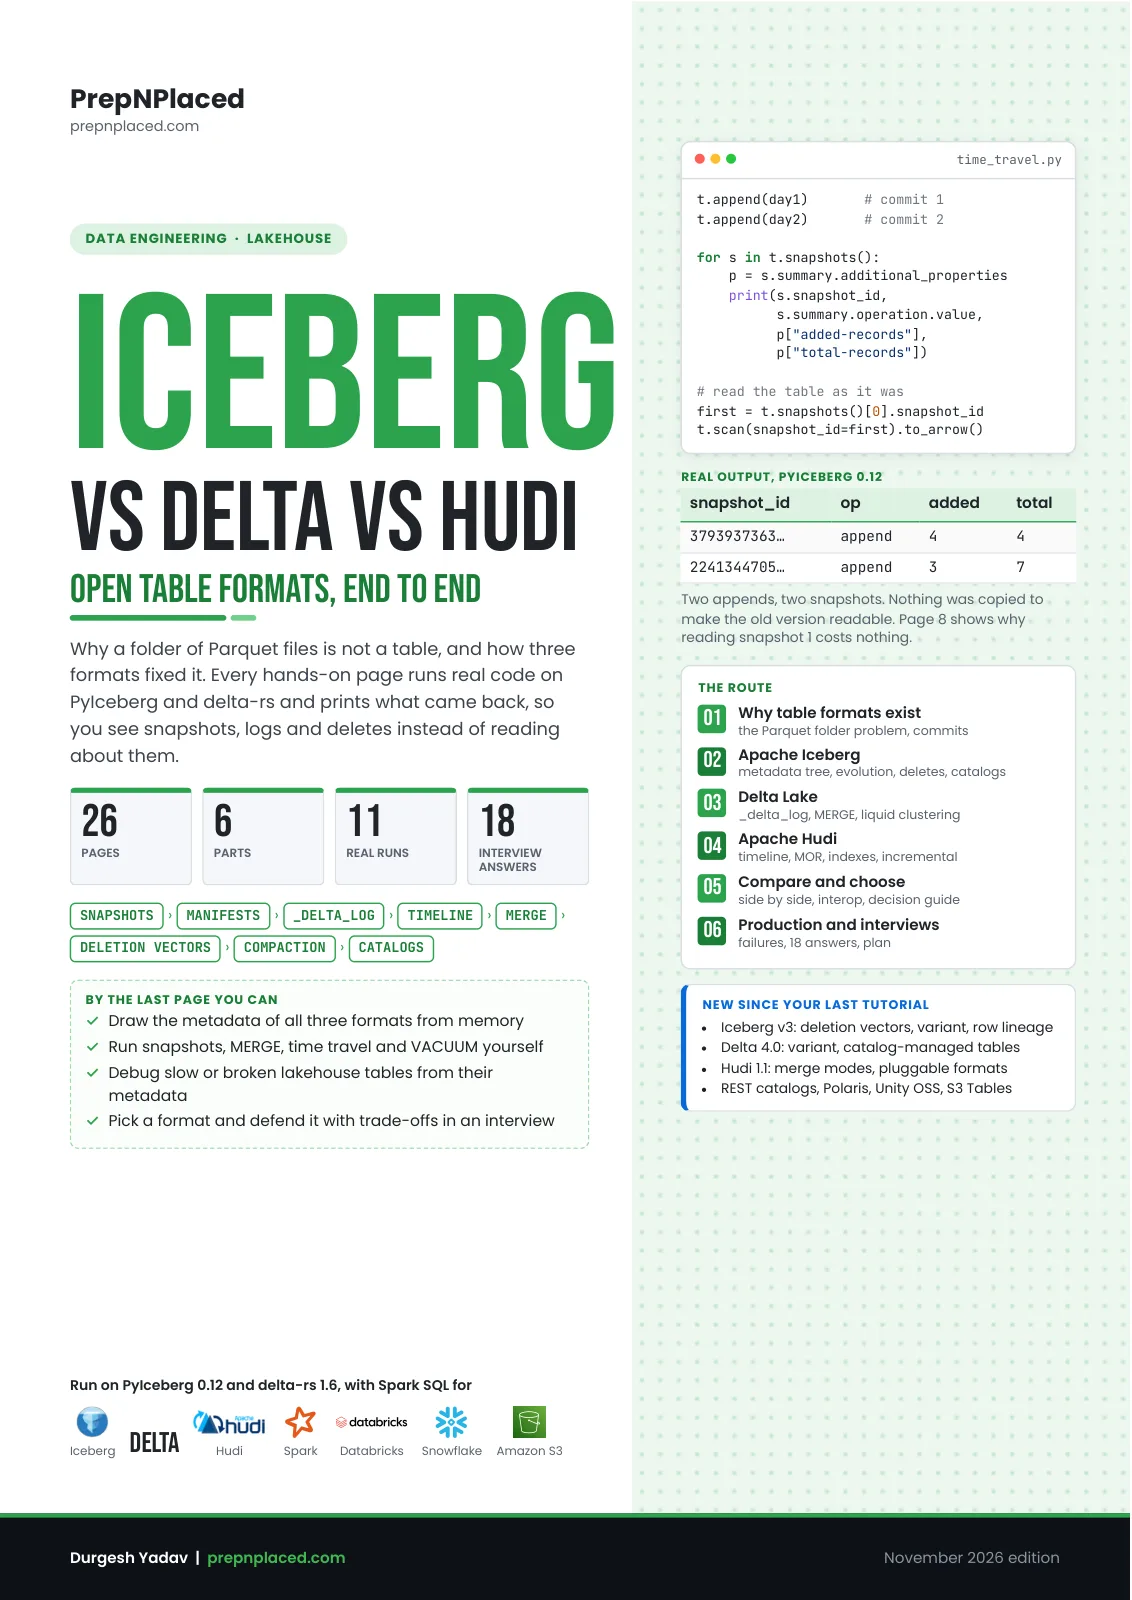 Architecture
Iceberg vs Delta vs Hudi — Open Table Formats
Why a folder of Parquet is not a table, and how Iceberg, Delta and Hudi fix it. Snapshots, logs and deletes run for real on PyIceberg and delta-rs.
26 pages510 KB
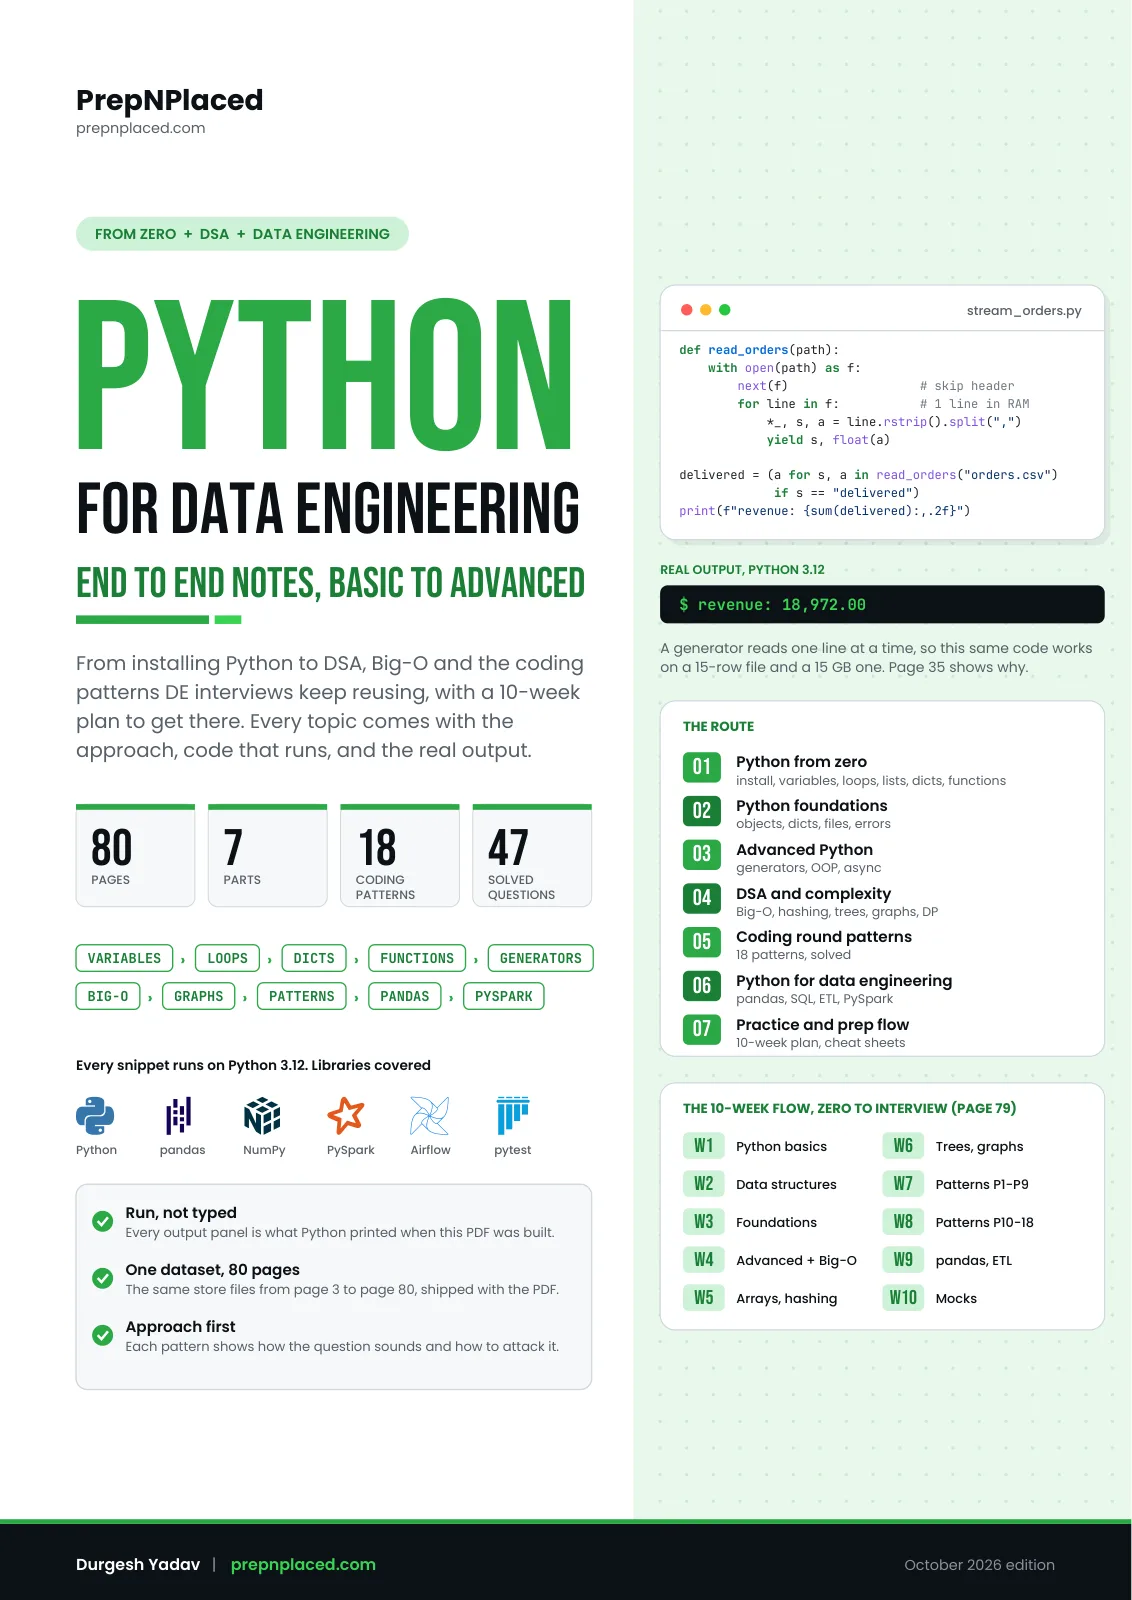 Python
 for Data Engineering — End to End Notes
From installing Python to DSA, Big-O and the coding patterns DE interviews keep reusing, with a 10-week plan to get there. Every topic comes with the approach, code that runs, and the real output.
80 pages477 KB
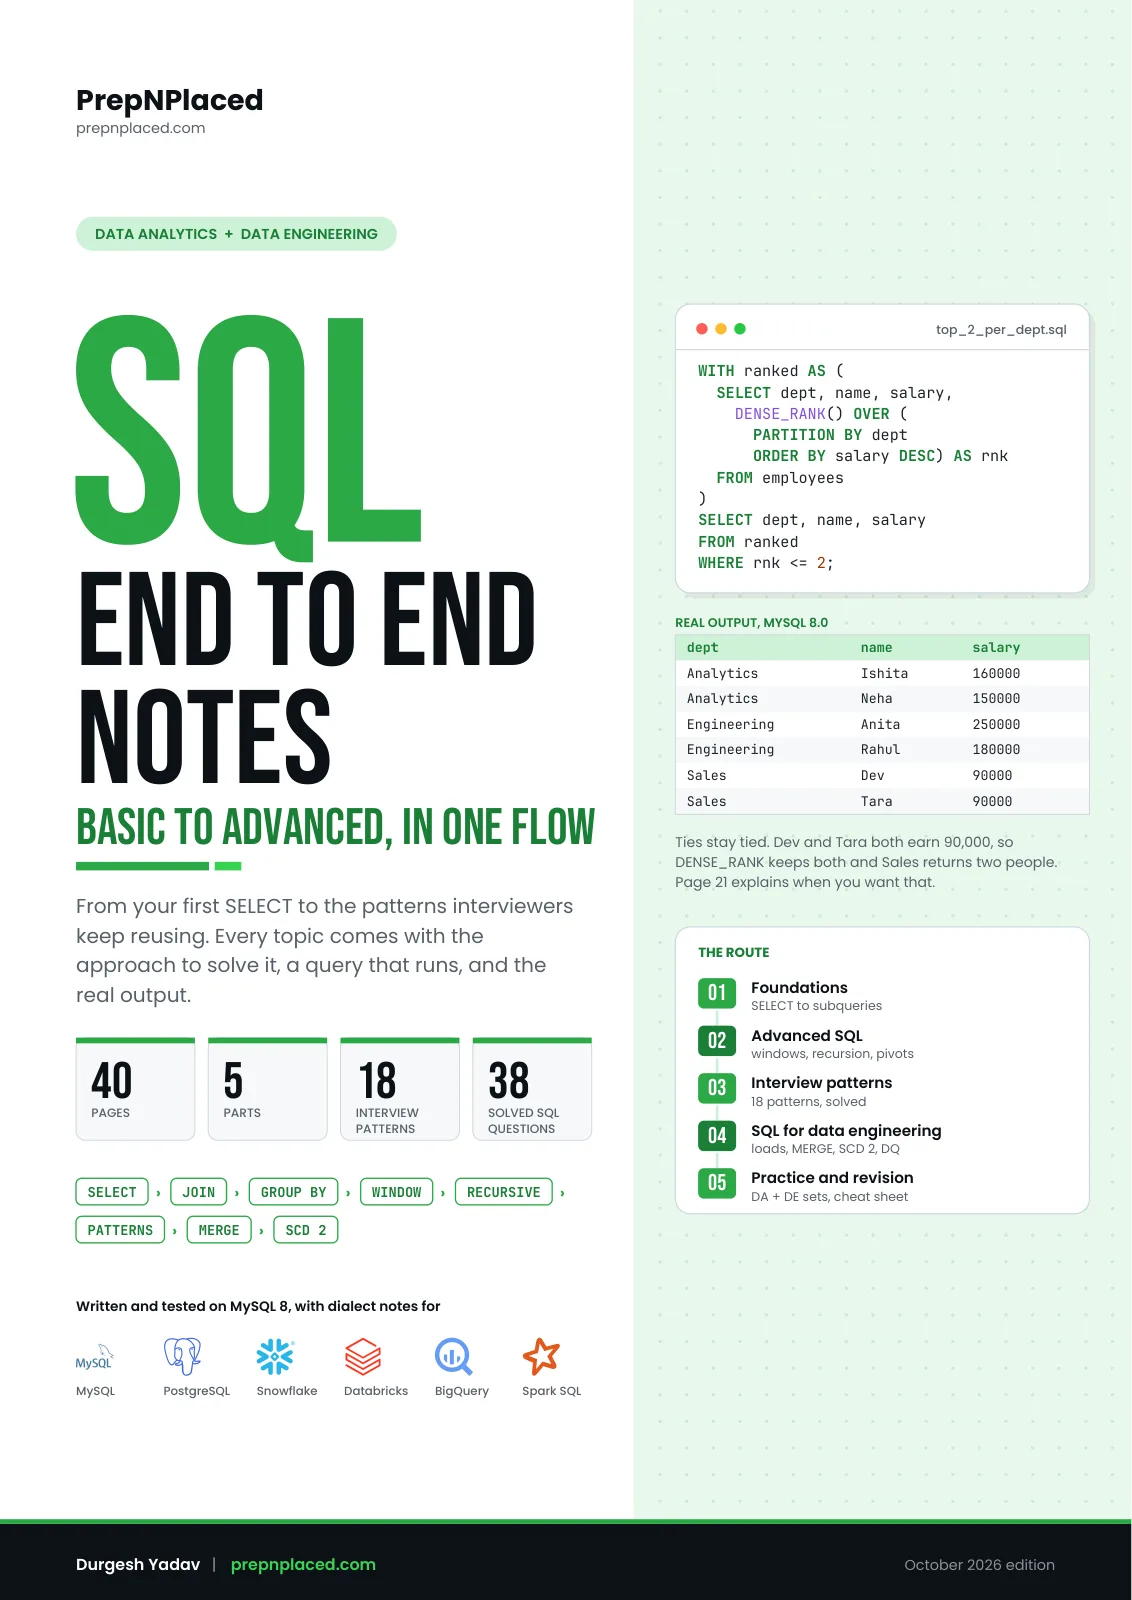 SQL
SQL — End to End Notes
From your first SELECT to the patterns interviewers keep reusing. Every topic comes with the approach to solve it, a query that runs, and the real output.
40 pages329 KB


 Fundamentals Popular
Data Engineering: From Zero to Production & Interview Ready
Lecture Zero plus fourteen chapters — Linux, SQL, Python, data modeling, storage, cloud, pipelines, Spark, Airflow, Kafka, data quality, a portfolio project and the interview loop. Every figure measured. Free, and it never uses your free note.
244 pages1.4 MB


 GitLab & CI/CD Popular
GitLab for Data Engineers — Complete Notes
Twenty pages on how your code actually reaches production: Git and merge requests, .gitlab-ci.yml line by line, rules and runners, dbt Slim CI without dbt Cloud, shipping Airflow DAGs and Databricks asset bundles, plus 25 rapid-fire interview questions.
20 pages1.6 MB
 PySpark Popular
PySpark on Cricket Data — Complete Notes
The full written notes from the 29 August live build: loading raw IPL match data into Databricks, DataFrame analysis with groupBy, window functions, joins and UDFs, tuning with caching and partitioning, and writing the processed outputs to Delta.
20 pages1.8 MB




Two free ways to see where you stand
After the notes
Notes get you through the revision. These get you through the interview.
Read them in order if you like — the free library first, then the deep-dive modules, then the live cohort when you want someone reviewing your work.
Free · no payment
Watch the lessons behind the notes
SQL, Python, Power BI, PySpark and Excel — full video lessons with MCQs and a proctored skill test at the end. The notes are the summary; this is the teaching.
Open the free libraryLearn Pass · ₹499 for 6 months
23 deep-dive modules, 74 sessions
Every note in this vault for 6 months, plus the complete PySpark and Databricks modules recorded end to end with their project notebooks. One payment, nothing renews.
See what's insideAI-Powered Data Engineering Cohort 4 · live cohort
The live data engineering cohort
Live weekend classes (Sat–Sun · 7 AM–9:30 AM IST), real projects, graded assignments, and 6 months of Pro Auto-Pilot included. The full path, taught with you in the room.
See the curriculumYour first note and the free book cost nothing. The rest of the vault comes with the Learn Pass, any paid plan or a cohort seat.