Free samples are marked, so press play. The rest is the premium shelf: ₹99 buys one session's recording and its resources, and the Learn Pass (₹499) opens the whole shelf for 6 months. Every recording published up to the end of your 6 months stays yours. The Data Modelling module is the one exception: it is sold on its own.
Also included: the notes vault, Project Lab and one Score Your LinkedIn pack. One payment, nothing renews.
Last updated 1 Nov 2026 · 6–8 new videos every month
Premium modules · Learn Pass
Complete modules, lecture by lecture
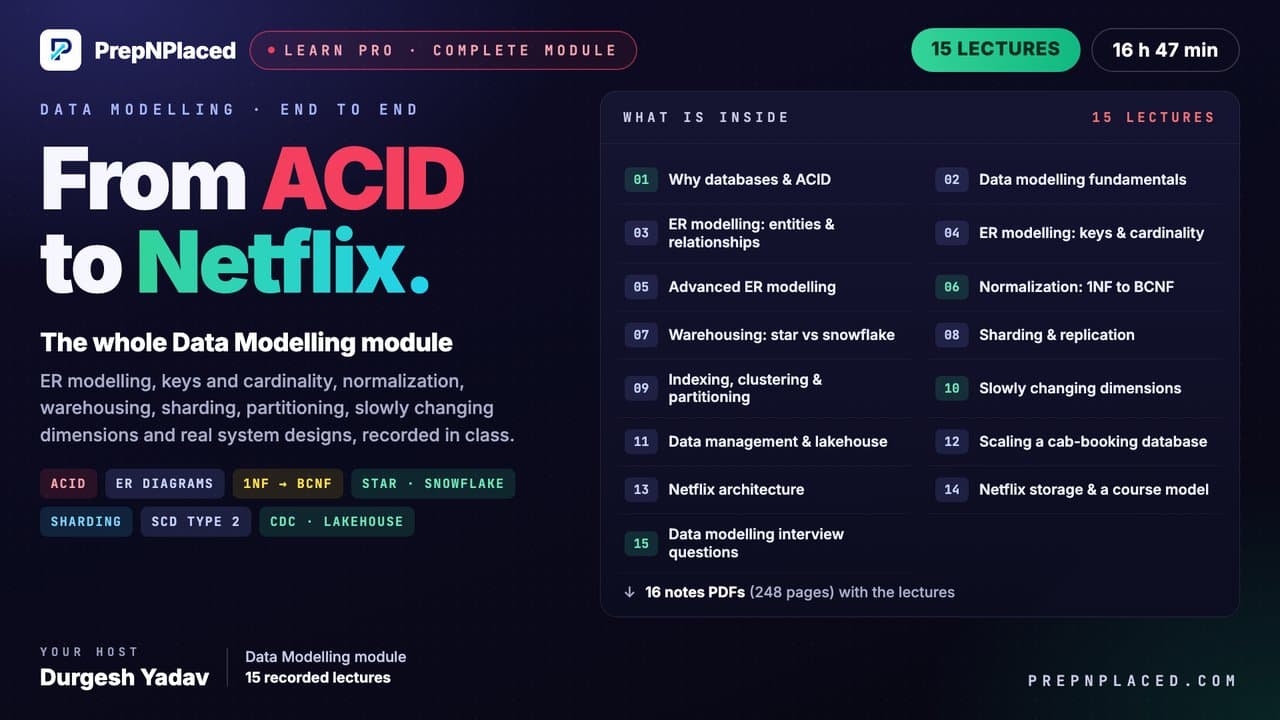
15 lectures · 16 hours 47 minutes₹499 after approval
Data Modelling
Fifteen lectures recorded in class with Durgesh Yadav, with 16 PDFs of notes (248 pages). It starts with why databases exist: indexing, schema enforcement, MERGE upserts and ACID. Then the data model itself: the three levels, attributes, keys and cardinality, ER modelling from entities and relationships to specialisation, generalisation and aggregation, and normalization from 1NF to BCNF. Then warehouses and scale: storage and compute, ETL and ELT, star and snowflake schemas, sharding and replication, indexing, clustering and partitioning, and slowly changing dimensions with MERGE. It ends with real designs (data management with Unity Catalog, CDC and the lakehouse, a cab-booking database at scale, Netflix's architecture and data storage, an online course data model) and data modelling interview questions.
Data Engineering · Data Modelling
Checking your access…
1 lecture · 0 resourcesLearn Pass · ₹499
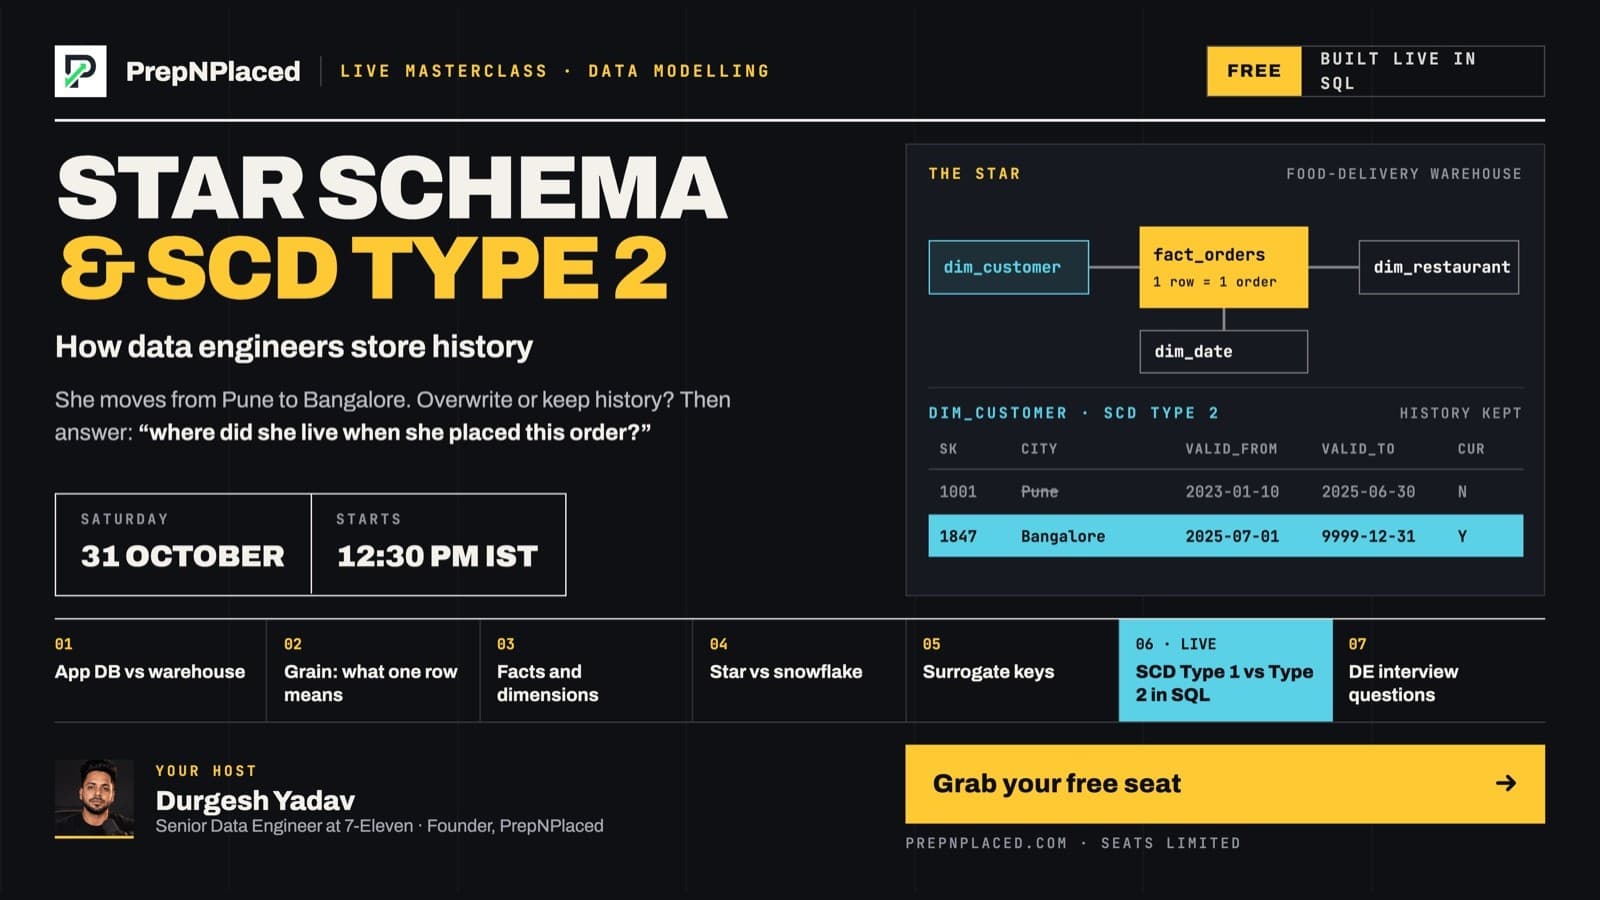
Star Schema & SCD Type 2
Recorded live on Saturday 31 October 2026. A whiteboard class on how data engineers store history, worked through an online store's order system. It starts with the questions the business asks, then OLTP versus OLAP: why a query over 12 months of orders slows the one server behind a MySQL or Postgres database, and how each day's orders land as a file in S3, ADLS or GCS for a warehouse like Databricks to read with Spark. Then the star schema: product, store, customer and date dimensions around one orders fact table, and the snowflake schema that splits addresses into their own table. Next is grain: what one row of a fact table represents, the order_id plus product_id composite key, and how a count without DISTINCT double counts orders. After factless fact tables, shown with student attendance, it turns to slowly changing dimensions as customer Rahul moves from Delhi to Bangalore: SCD Types 0 to 3, surrogate keys, and the effective_start_date, effective_end_date and is_current columns that Type 2 adds.
Data Modelling · Data Engineering
1 lecture · 1 resourceLearn Pass · ₹499
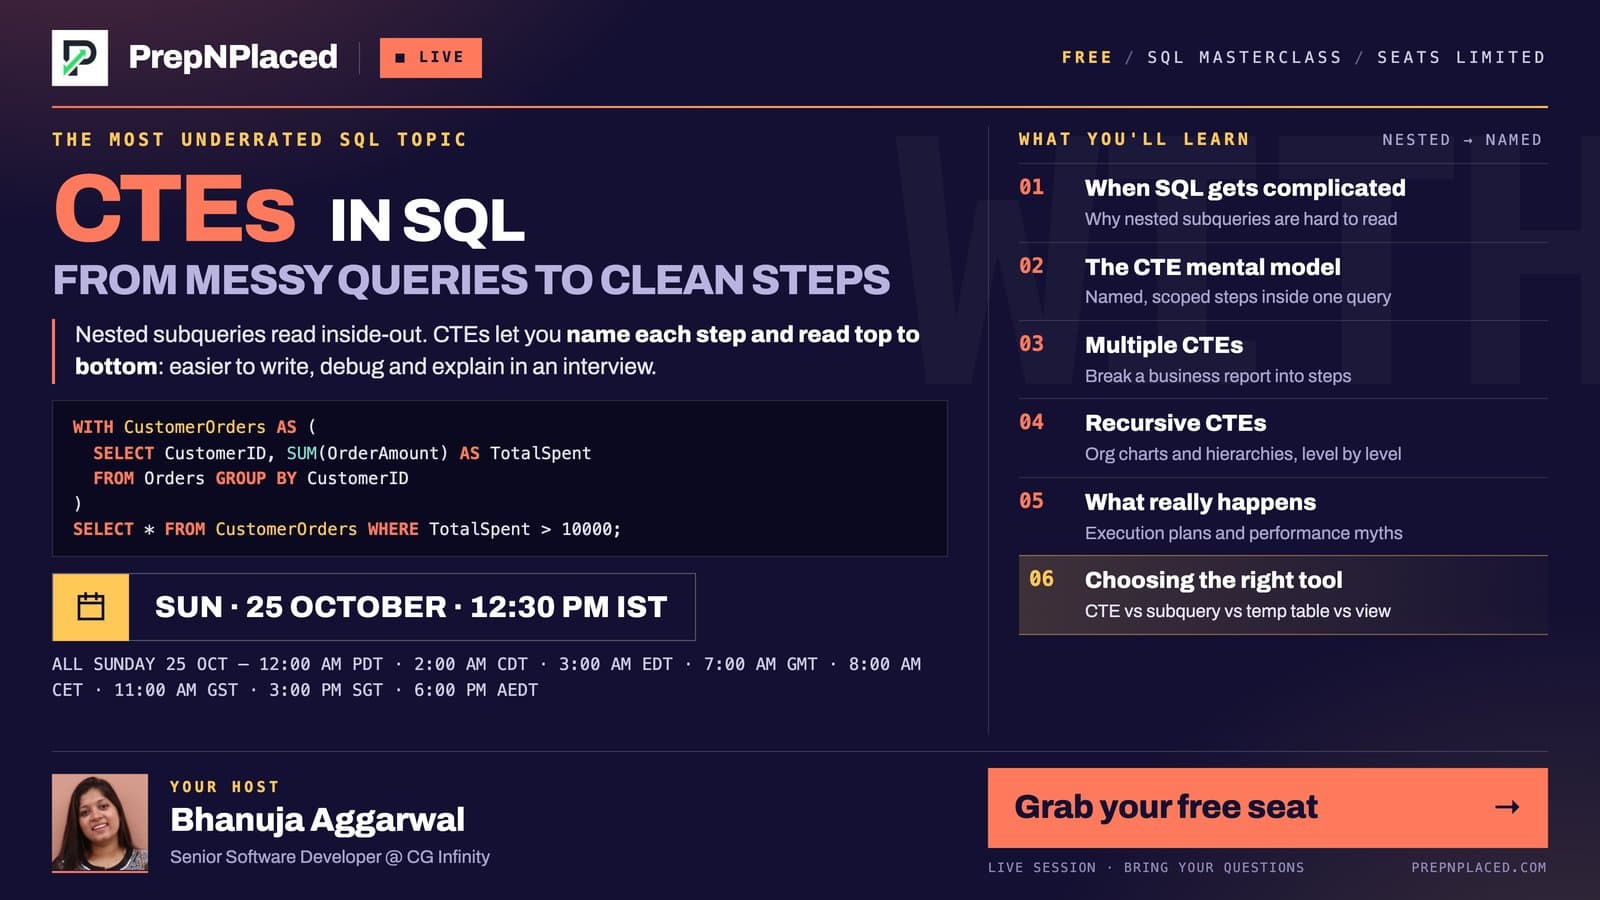
CTEs in SQL
Recorded live on Sunday 25 October 2026 with Bhanuja Aggarwal, Senior Software Developer at CG Infinity. It starts from a query that has become hard to follow and rewrites it with a CTE, then takes one apart: WITH, the name, the inner query, the closing parenthesis and the one statement allowed to use it. From there it chains several CTEs to break a report into steps, and builds recursive CTEs, first counting numbers and then walking an org chart from the CEO down, level by level, with the recursive member, the iterations and the point where it stops. Each step runs live in the Databricks SQL editor. It closes on a table that sets a CTE against a subquery, a temp table and a view: what each is for, where it can be reused, whether its results are stored, and its limits. Comes with the 9-page slide deck.
SQL · Data Analytics & Engineering
1 lecture · 1 resourceFree
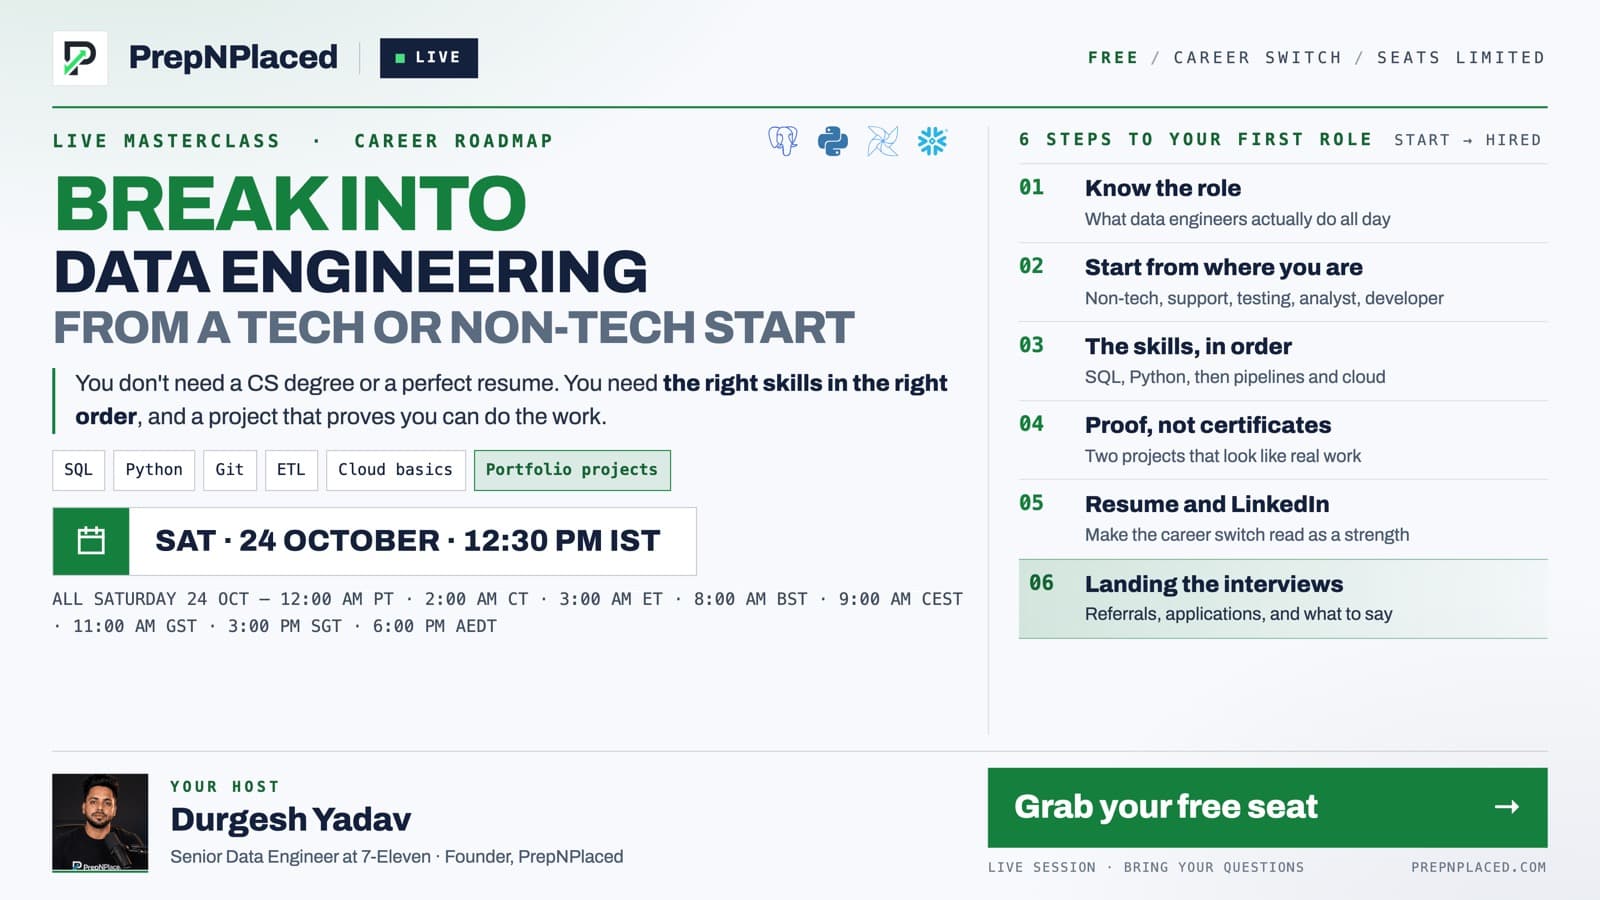
Break Into Data Engineering
Recorded live on Saturday 24 October 2026. The two breaks and the long pauses are cut, so it runs 1 hour 4 minutes. A whiteboard session for people moving into data engineering from another role. It starts with five questions an e-commerce owner asks and why scattered, messy data stops anyone answering them, then goes through the data engineering life cycle: collect, ingest, clean, transform, store, use. It covers how analyst, engineer and scientist roles differ, what a daily 8 AM revenue report pipeline has to handle (changed orders, late data, duplicates, a run that fails halfway, cloud cost), how a startup grows from one PostgreSQL server to OLTP plus a data warehouse, ETL and ELT, and what makes a pipeline production ready. It closes with the order to learn the skills in: SQL first, then Python for automation and data processing, then databases and data modelling. Comes with the Modern Data Engineering Roadmap 2026-2027.
Career Roadmap · Data Engineering
1 lecture · 1 resourceFree
Real PySpark in Production for Real Interviews
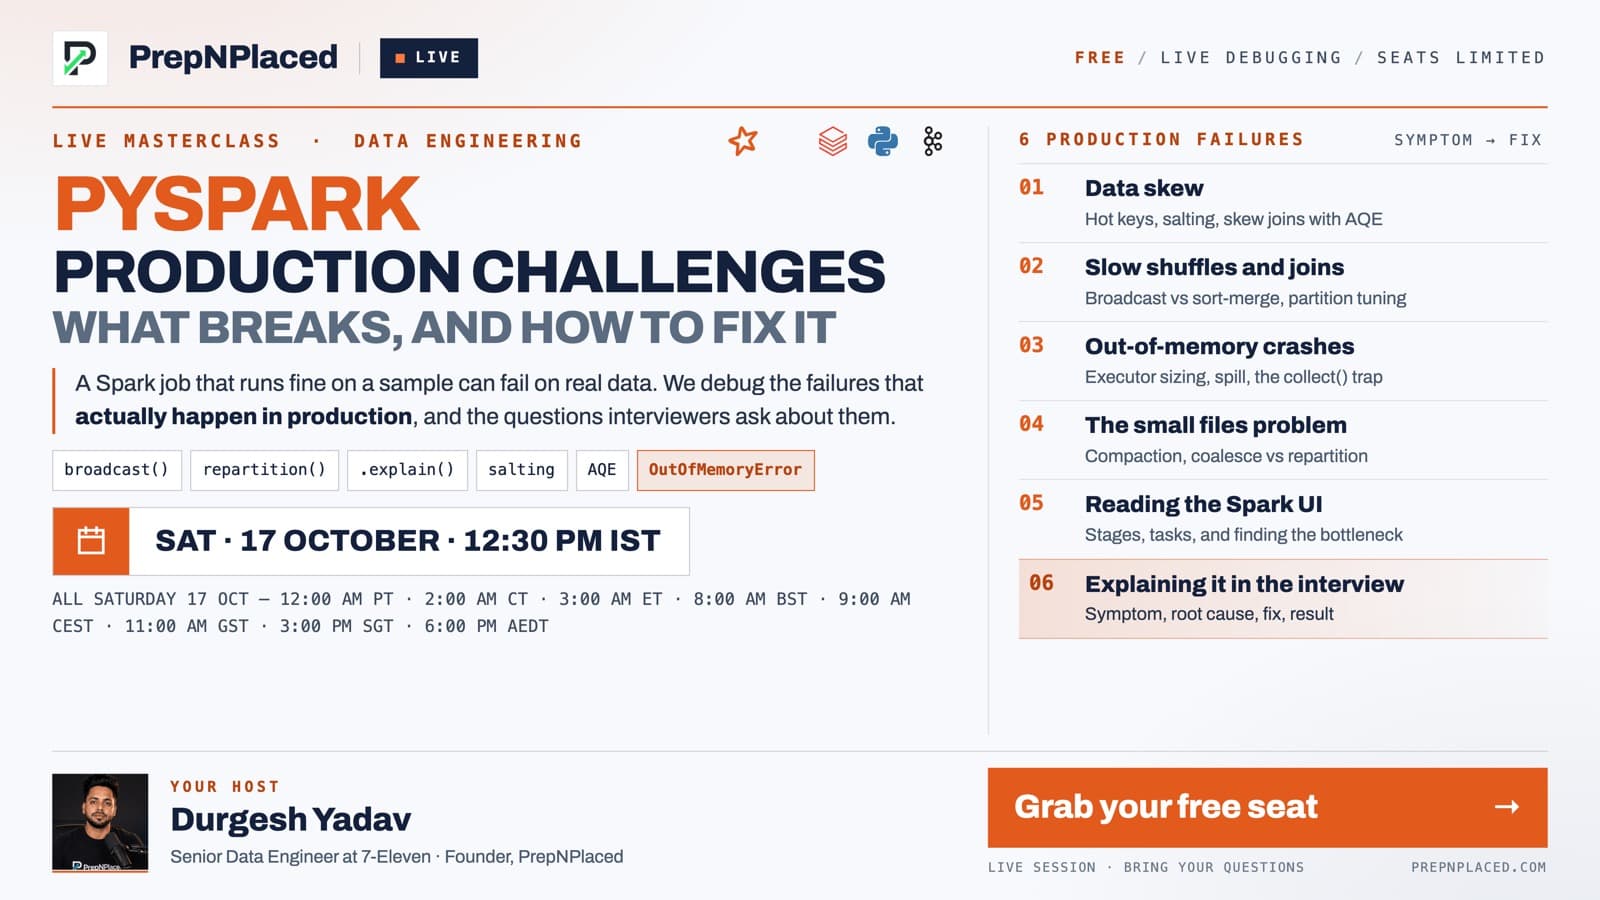
Recorded live on Saturday 17 October 2026. A whiteboard class on what Spark does with your job on production data. It starts from a daily sales report that runs in 20 seconds on a sample, then hits an out of memory error in production and takes 2 to 3 hours. Then inside Spark: the driver, the Catalyst optimiser and lazy evaluation, jobs, stages and tasks, how a 100 GB file becomes 800 partitions that 16 cores work through in 50 rounds, how an executor splits its memory, when a shuffle happens, and why collect() can crash the driver. Comes with the 69-page notes, PySpark in Production: the parts nobody teaches, which go further: skew, join plans, spill, small files and the Spark UI.
Data Engineering · PySpark
1 lecture · 0 resourcesLearn Pass · ₹499
Python Interview Questions for Data Engineers & Analysts
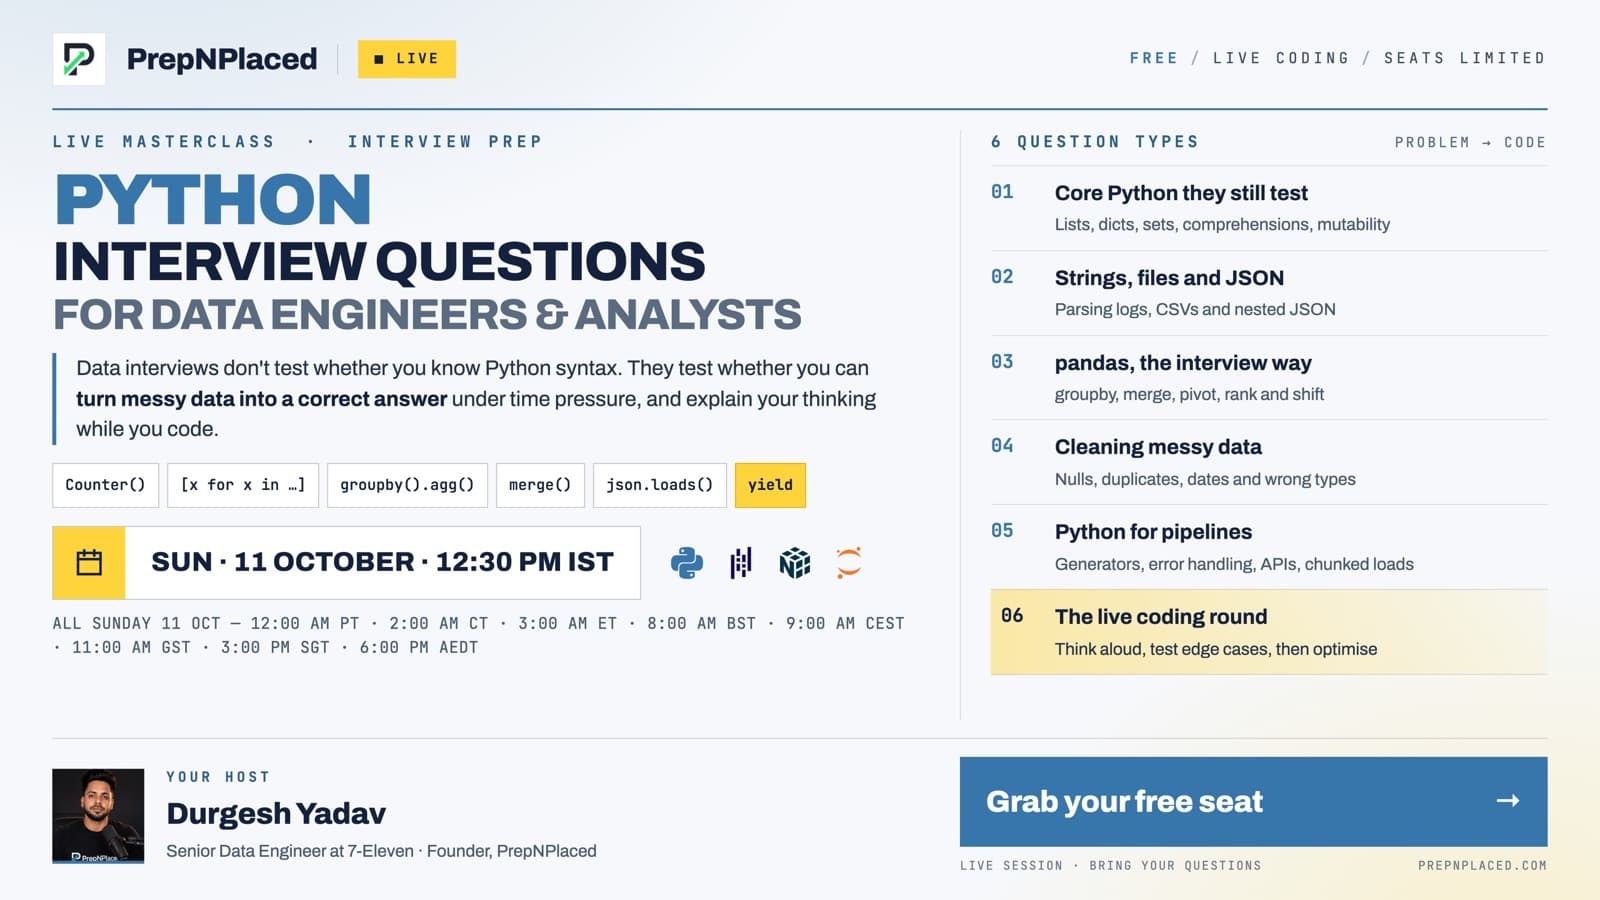
Recorded live on Sunday 11 October 2026. Python problem solving the way a data engineering interview asks it. It opens with why loops, list comprehensions and lambdas still matter in a data job (a pipeline that picks the latest daily sales file out of a folder before PySpark takes over), why interviewers care how many loops your code needs, and where OOP and low-level design fit. Then, live in a Colab notebook: find the duplicate records in a list, first with a nested count and then in one pass with a set, and find the second highest distinct salary, including the cases that break the first attempt: a starting value of None, and a list where every salary is the same.
Python · Data Interviews
1 lecture · 2 resourcesLearn Pass · ₹499
Part 2 - Tesla Telemetry Pipeline
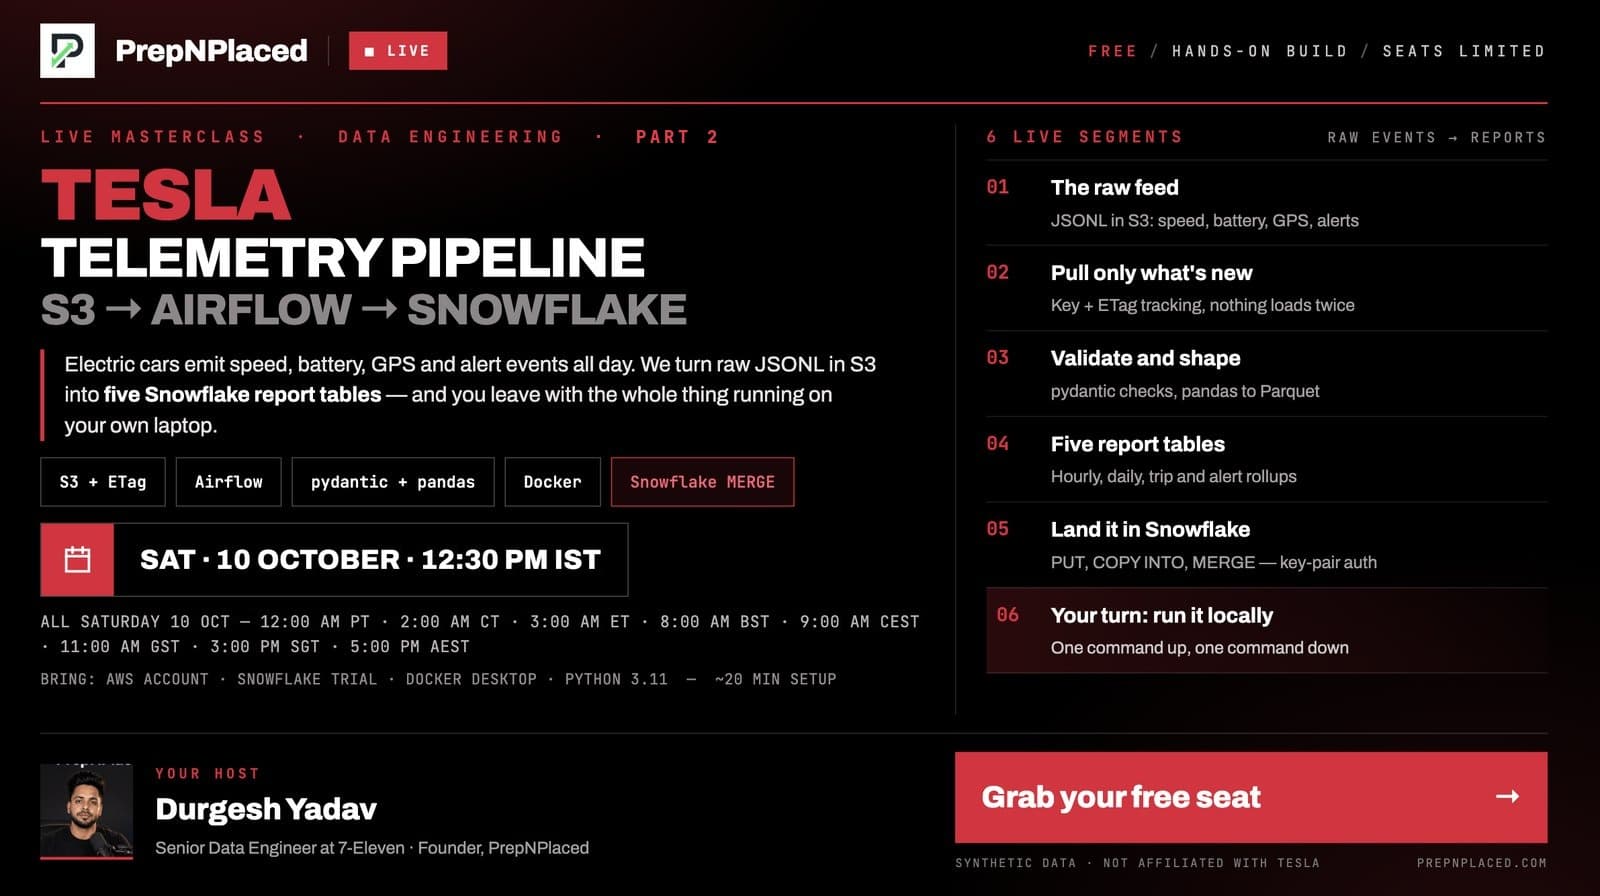
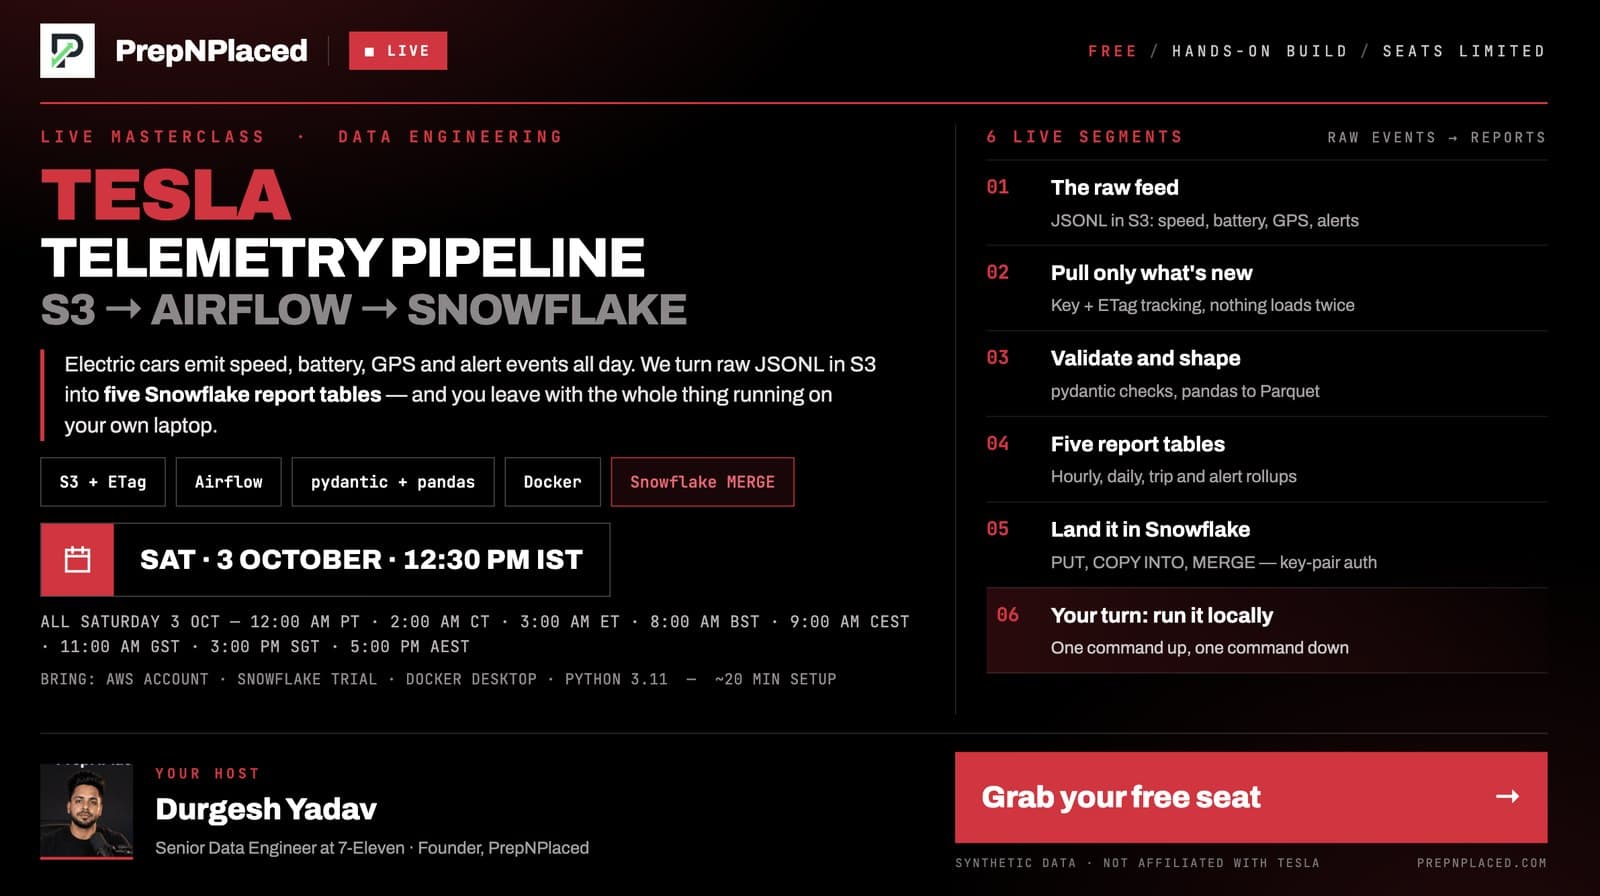
Part 2 of the Tesla Telemetry Pipeline session, recorded live on Saturday 10 October 2026: the explanation half. It reads the project's own walkthrough from start to end: the idea in five sentences, the big picture from the S3 raw zone through the Airflow DAG to Snowflake, what one telemetry event holds, and what every folder and file is for. Then the code, file by file: the DAG and its four tasks, the settings read from the .env file, pulling only the new files from S3, the quality checks, the pandas rollups, the Snowflake database, tables and MERGE procedure, the load through staging tables, and the docker-compose file that runs Airflow. Where private settings were on screen the picture is covered and the audio carries on. Comes with the same public GitHub repo and run guide as Part 1, which was recorded on Saturday 3 October 2026.
Data Engineering · Hands-On Build
1 lecture · 1 resourceLearn Pass · ₹499
SQL Patterns That Crack Product Company Interviews
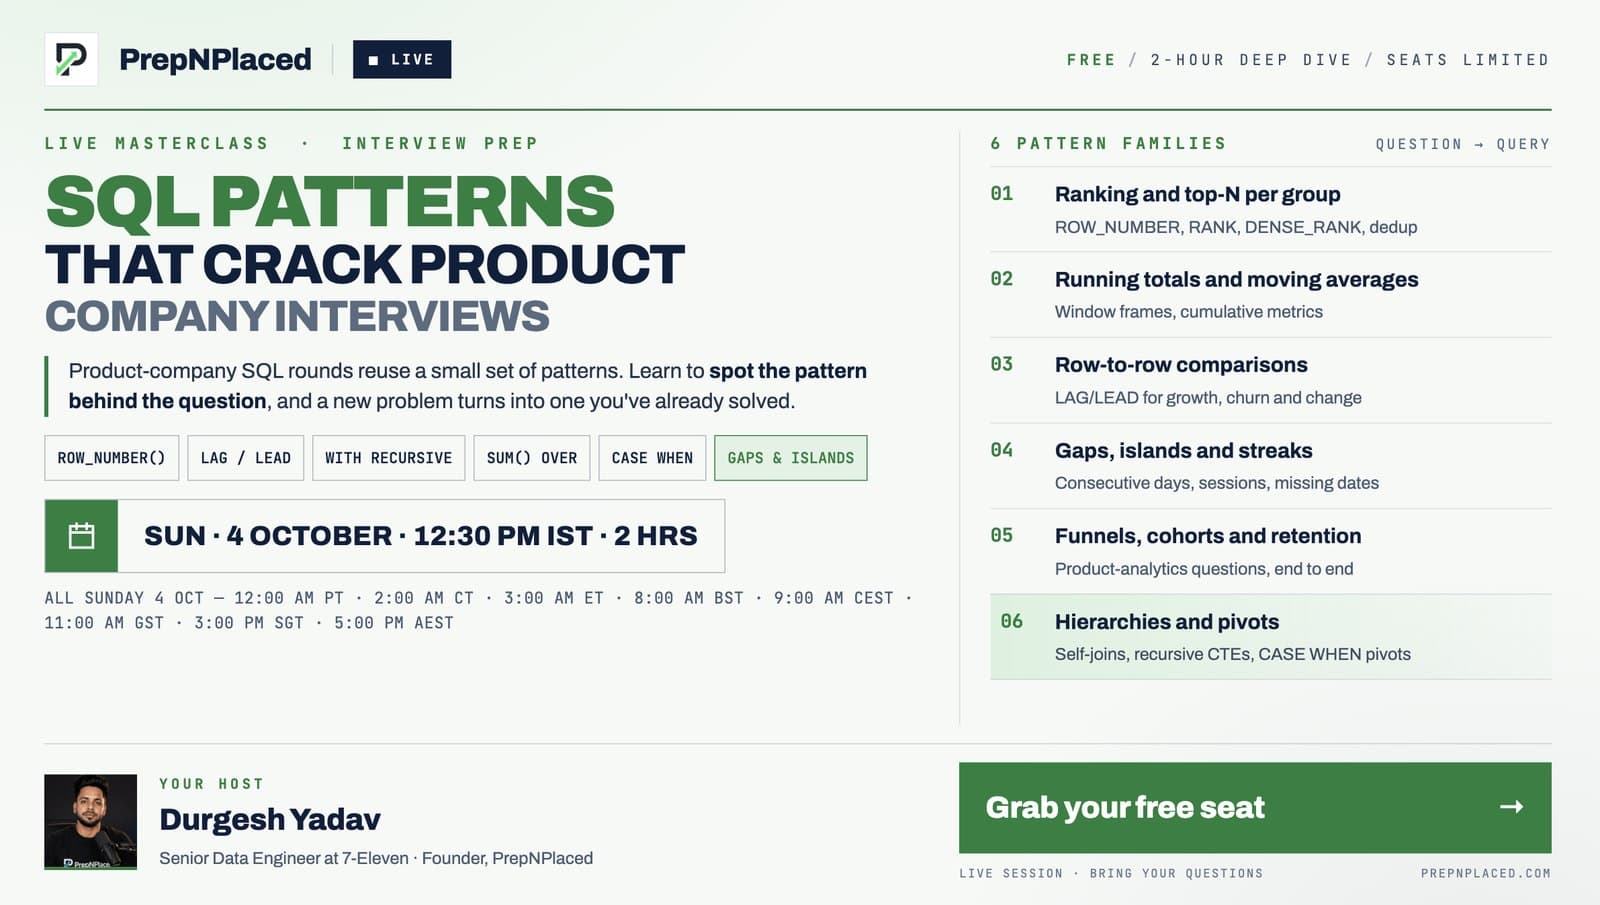
Recorded live on Sunday 4 October 2026. The pattern families that keep coming up in product-company SQL rounds: how to recognise each one from the wording of a question, and the query shape that solves it. Comes with the 40-page SQL End to End Notes as a PDF.
SQL · Product-Company Interviews
1 lecture · 2 resourcesLearn Pass · ₹499
Part 1 - Tesla Telemetry Analysis
Part 1 of the Tesla Telemetry Pipeline session, recorded live on Saturday 3 October 2026. It walks through the project in plain words, then sets it up from scratch on a Windows laptop: the S3 bucket and the sample file, an AWS access key, a Snowflake trial and its account details, the .env file, and installing Docker Desktop with WSL 2. Where keys were on screen the picture is covered and the audio carries on. Comes with the public GitHub repo and a run guide that takes you from git clone to five report tables in Snowflake on your own laptop in about 2 hours. Part 2, the explanation, is a separate live session on Saturday 10 October 2026 at 12:30 PM IST.
Data Engineering · Hands-On Build
1 lecture · 1 resourceLearn Pass · ₹499
Data Engineer 2027: The Real Stack
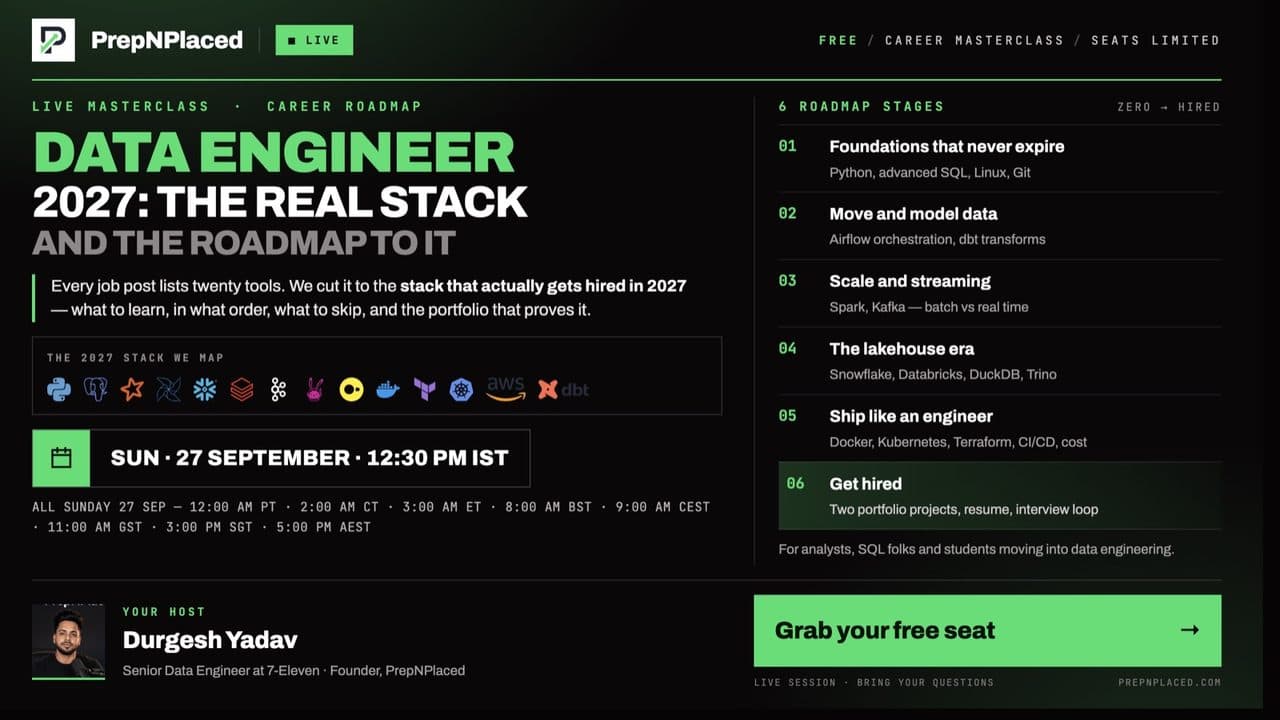
The 27 September session on the stack that actually gets data engineers hired in 2027, and the order to learn it in, so you stop collecting tutorials and start building toward a job. Comes with the Modern Data Engineering Roadmap 2026-2027: 20 stages from SQL to system design, 89 topics each with a practice task, a checkpoint after every stage, 6 portfolio projects for your GitHub, and the interview rounds decoded at the end. About 57 weeks at 12-15 hours a week.
Data Engineering · Career Roadmap
1 lecture · 2 resourcesLearn Pass · ₹499
Netflix System Design for Data Engineers
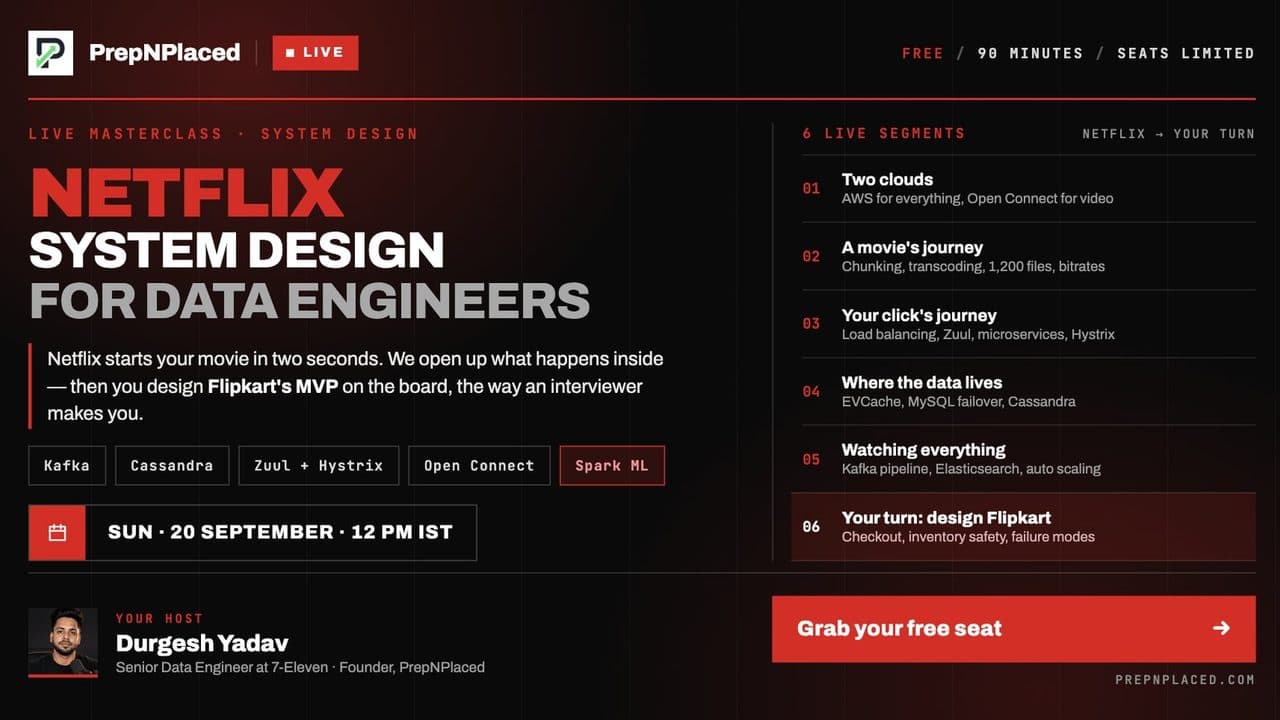
The full 20 September session. Most people learn system design as a list of tool names and twenty names in one sitting blur together. This gives you somewhere to hang them: four questions every big system answers, answered live for Netflix — the two clouds, a movie's journey to roughly 1,200 output files, your click's journey across 2,200+ device types, EVCache, MySQL and Cassandra, and the Kafka event pipeline that watches it all. The last segment is yours: Flipkart's MVP designed on the board, scope to failure modes, the way an interviewer makes you. Comes with the instructor's System Design document.
System Design · Data Engineering Interviews
2 lectures · 0 resourcesLearn Pass · ₹499
Your Non-Tech Experience Isn't a Gap
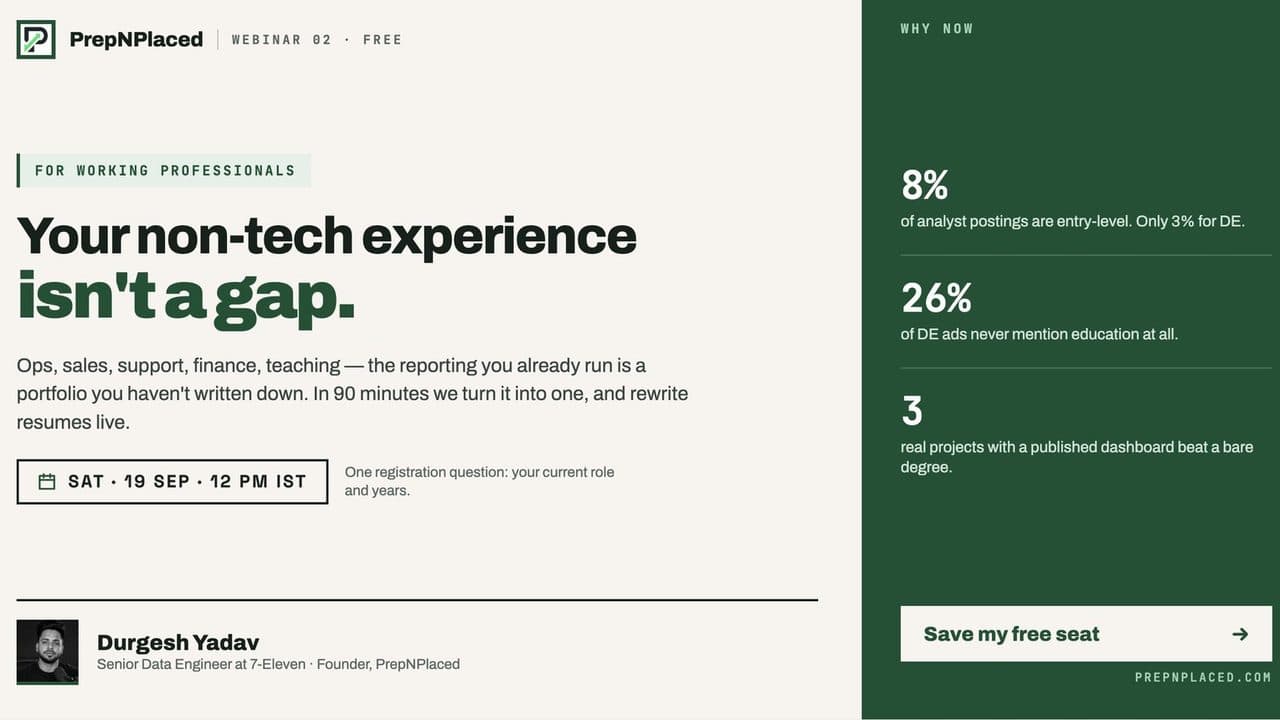
The full 19 September session in two parts, for people who already work. Only 8% of analyst postings are entry-level and 3% for data engineering, so applying to the entry-level door is the wrong move; 26% of DE ads never mention education at all, so the degree is rarely the blocker. What does move is three real projects with a published dashboard and a short write-up. Two hours turning the reporting, stakeholders and business context you already handle into exactly that, plus resume rewrites live on real profiles from the room.
Career Switch · Data Analyst & Data Engineer
1 lecture · 0 resourcesLearn Pass · ₹499
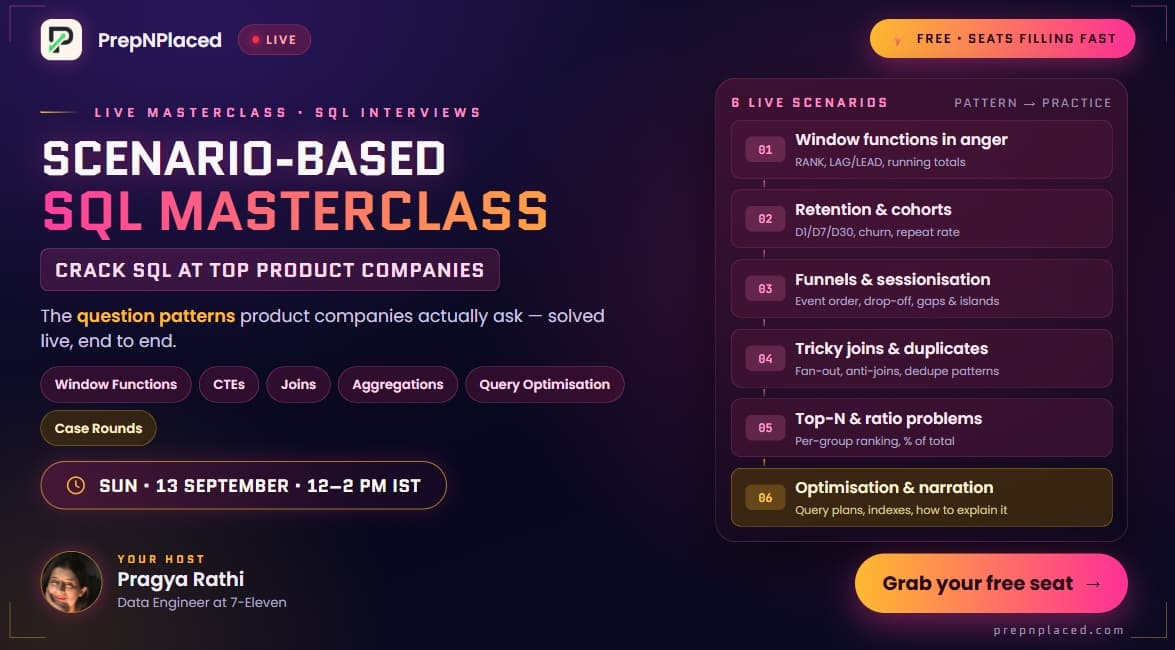
Scenario-Based SQL Masterclass
The full 13 September session. Product-company SQL rounds are not a hundred random questions — they are built on a handful of patterns, and once you see the pattern in the first thirty seconds the query writes itself. Two hours, six live scenarios: window functions in anger (RANK, LAG/LEAD, running totals), retention and cohorts (D1/D7/D30, churn, repeat rate), funnels and sessionisation (event order, drop-off, gaps and islands), tricky joins and duplicates (fan-out, anti-joins, dedupe), top-N and ratio problems (per-group ranking, % of total), then optimisation and narration — query plans, indexes, and how to explain your answer the way interviewers actually score it. Ends with live Q&A on SQL rounds and case interviews.
SQL · Product-Company Interviews
1 lecture · 1 resourceLearn Pass · ₹499
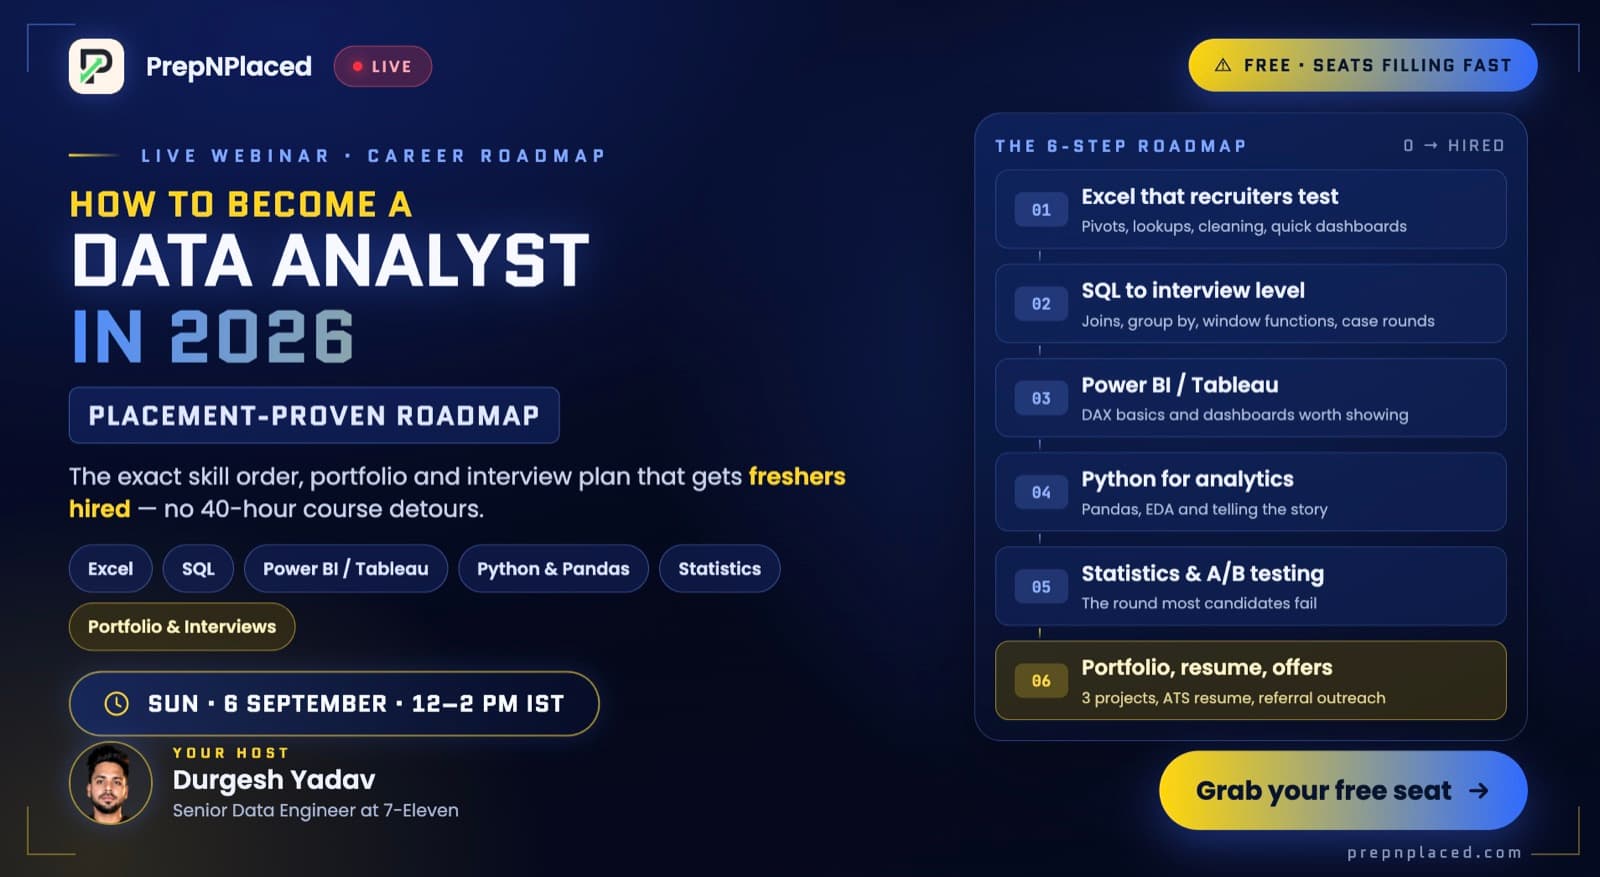
How to Become a Data Analyst in 2026
The full 6 September session — the exact skill order that converts to offers: the Excel recruiters actually test, SQL to interview level, statistics and the A/B round most candidates fail, pandas for real analysis, a dashboard worth showing, then the portfolio, resume and referral plan that closes it. Comes with the 20-page Data Analytics Roadmap 2026: six phases across 24 weeks, each ending in an exit test, plus 8 worked SQL problems, the 7 A/B traps and 30 rapid-fire interview answers.
Data Analytics · Career Roadmap
1 lecture · 3 resourcesLearn Pass · ₹499
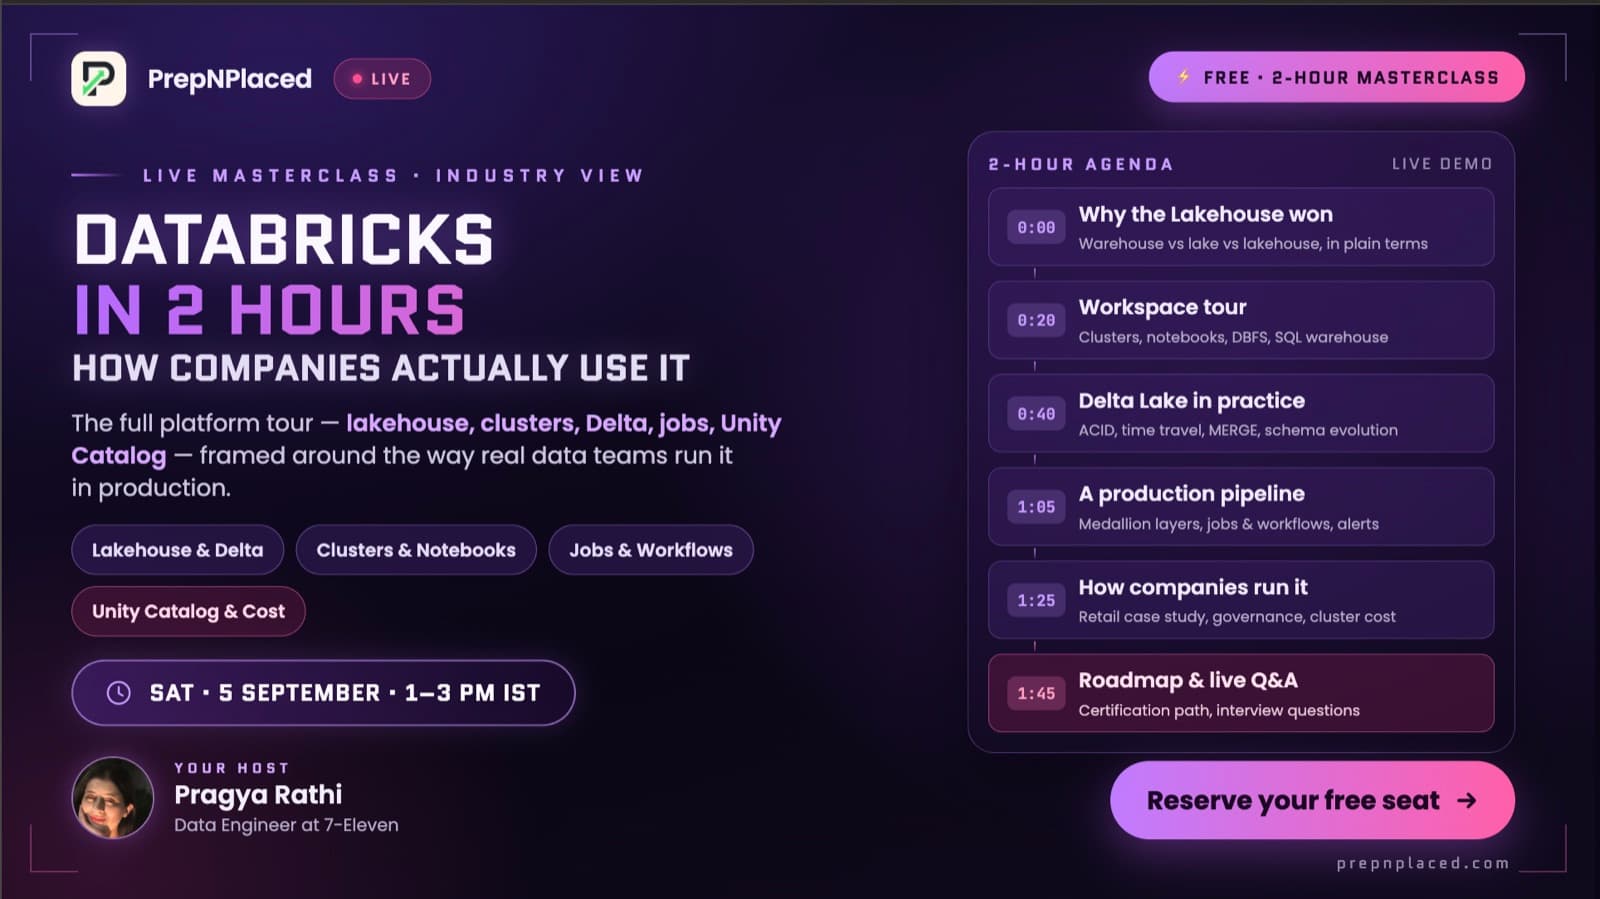
Databricks in 2 Hours — How Companies Actually Use It
The full 5 September session — why teams outgrow Excel and SQL Server, data lake vs warehouse vs lakehouse, the workspace (notebooks, compute, Spark), CSV vs JSON vs Parquet vs Delta, medallion Bronze → Silver → Gold and jobs & workflows — then the hands-on project on a sales dataset. Comes with the 15-page session notes, the class CSV and an importable Bronze → Silver → Gold notebook.
Data Engineering · Databricks
1 lecture · 1 resourceLearn Pass · ₹499
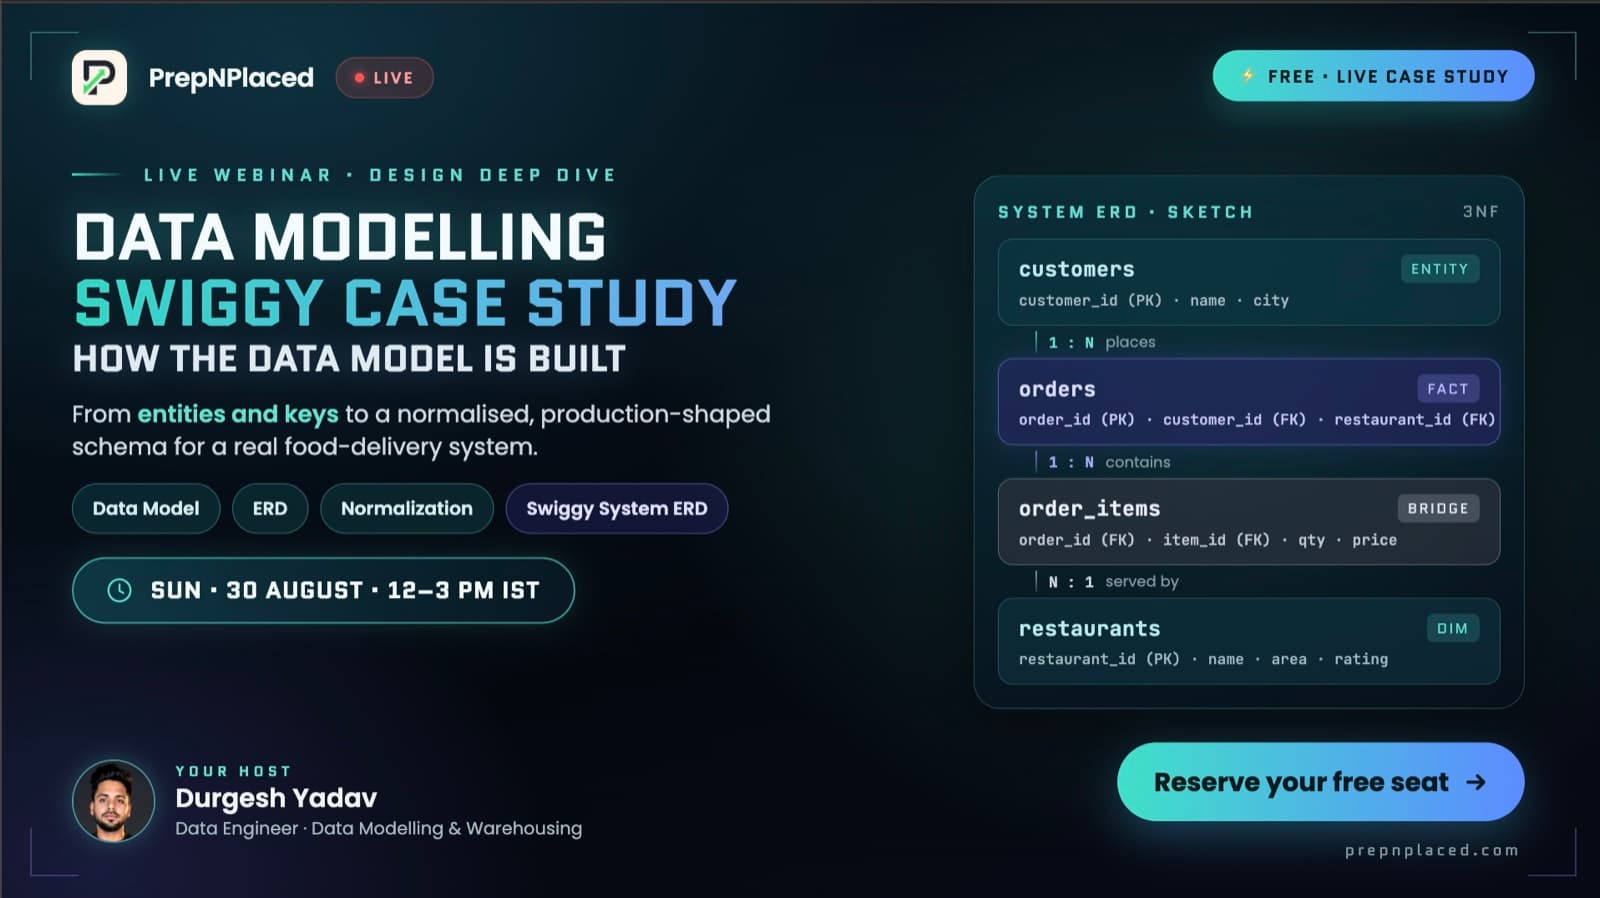
Data Modelling Basics
The full Data Modelling session — entities, keys, cardinality and normalization built into Swiggy's schema live — with the 20-page ER Model & ER Diagrams notes: every symbol, strong vs weak entities, ISA, aggregation, and five real company ERDs worked end to end.
The complete IPL build from the 29 August session: raw ball-by-ball cricket data landing in Databricks, modelled Bronze → Silver → Gold through a modular PySpark pipeline you can run yourself. Comes with the class dataset, the four notebooks that build each layer, and the full written notes — plus the three Databricks sessions a beginner needs first.
The full medallion build from the 23 August session: raw vendor payout and store POS files landing in AWS S3, modelled Bronze → Silver → Gold on Databricks into a payment reconciliation you can demo. Comes with the complete project bundle — notebooks, datasets, SQL, workflow config and a step-by-step beginner guide — plus the four prerequisite sessions.
Data Engineering · Databricks
5 lectures · 0 resourcesFree
SQL Interview Questions — 5 Lectures
Five sessions of SQL interview questions worked end to end — read the question, write the query, then talk through why it is the right shape. Watch in order.
SQL
1 lecture · 1 resourceLearn Pass · ₹499
LLMs & Agentic AI for Data Engineering
The full session on LLMs and agentic AI in data engineering workflows, with the hand-drawn 25-page field notebook that goes with it — the four pillars: LLM fundamentals, prompt engineering, RAG and tool calling.
AI · Data Engineering
1 lecture · 4 resourcesFree
Azure Data Engineering — End-to-End Project
The complete build with Abhinav Singh: Azure SQL through a metadata-driven Data Factory loop into ADLS Gen2, then Databricks modelling it Bronze → Silver → Gold in Unity Catalog. Comes with the project files, the architecture, the prerequisites and a practice brief.
Data Engineering · Azure
5 lectures · 4 resourcesLearn Pass · ₹499
Complete PySpark Module
Five full lectures from zero to a real PySpark project — plus the project notebook, and the optimisation and joining guides as PDFs.
Data Engineering · Big Data & Spark
3 lectures · 0 resourcesLearn Pass · ₹499
Complete Databricks Module
Three end-to-end Databricks sessions — the platform, the lakehouse workflow, and building on it like a data engineer.
Data Engineering · Databricks
5 lectures · 0 resourcesLearn Pass · ₹499
Complete AWS Cloud Module
Five sessions from what the cloud actually is to the AWS services a data engineer uses every day — IAM, EC2, S3, RDS, Lambda and the CLI.
Data Engineering · AWS Cloud
Session recordings
Every webinar, watchable again
Webinar recordingFree sample
What is Cloud Computing? Introduction to AWS
Cloud fundamentals from zero — what the cloud actually is, why teams moved to it, and a hands-on first look at AWS.
Cloud · AWS
Webinar recordingFree sample
Python Introduction
Lecture 1 — your first lines of code: setup, syntax, variables and data types.
Python Fundamentals · Lecture 1
Webinar recordingFree sample
Python Strings
Lecture 2 — slicing, formatting and the string methods you'll use every single day.
Python Fundamentals · Lecture 2
Webinar recordingFree sample
Loops in Python
Lecture 3 — for, while, break and range: write code that repeats itself, properly.
Python Fundamentals · Lecture 3
Webinar recordingLearn Pass · ₹499
AWS RDS Explained
Managed databases in the cloud, end to end — setup, scaling and backups, and when RDS is the right call.
Cloud · AWS
Webinar recordingLearn Pass · ₹499
Azure Data Factory
Build, schedule and monitor real ETL pipelines — no code required. The tool most Azure data teams start with.
Data Engineering · Azure
Webinar recordingFree sample
What is Docker?
Containers, images, and why every data team is using them — explained from first principles.
DevOps · Docker
Webinar recordingFree sample
ETL, ELT & Medallion Architecture
Bronze → Silver → Gold: how modern data platforms are actually layered, and why the pattern won.
Data Engineering · Databricks
Full product demoFree sample
How to Use PrepNPlaced in 5 Steps
The full product walkthrough — every step from your first resume score to interview-ready, shown on the real platform.
Product demo
Project Lab · included with Learn Pass
Stop watching. Build the projects.
Guided, checkpoint-verified builds of real data-engineering projects — from installing Python to a live dashboard you can put on your résumé. Every step is explained for a complete beginner, your progress is saved, and a mentor answers your doubts on the exact step you are stuck on.
Hand-picked GitHub repositories matched to the modules — official sources, not random tutorials. Watch the module, then clone the repo and build the project it pairs with.
Capstone · End-to-end pipeline
Data Engineering Zoomcamp
The most-starred free DE curriculum on GitHub — build an end-to-end pipeline (ingestion, warehouse, orchestration, dbt, streaming) as your capstone portfolio project.
Unlocks with Learn Pass
PySpark · Databricks
Learning Spark v2 — official notebooks
Databricks' official companion notebooks — run them chapter by chapter after the PySpark lectures to cement DataFrames, joins and optimisation.
Unlocks with Learn Pass
PySpark · Reference
Apache Spark — examples directory
The source itself. Start in examples/src/main/python — small, runnable PySpark programs straight from the project that invented them.
Unlocks with Learn Pass
Azure · Data Factory + Databricks
Modern Data Warehouse DataOps (Microsoft)
Microsoft's official end-to-end Azure samples — Data Factory, Databricks and Synapse wired together with CI/CD, the production version of our Azure webinar build.
Unlocks with Learn Pass
Orchestration · Airflow
Apache Airflow — example DAGs
Orchestration the way interviews expect it. Read airflow/example_dags, then rebuild one of your own pipelines as a DAG.
Unlocks with Learn Pass
Analytics engineering · dbt
dbt Jaffle Shop
The classic dbt starter project — staging, marts, tests and docs on a toy business. The fastest way to make the dbt questions on our Top 1% paper feel easy.
Unlocks with Learn Pass
AWS · Serverless ETL
AWS Glue samples (official)
AWS's own Glue ETL examples — pair with the AWS Cloud module to turn IAM/S3/Lambda knowledge into a running serverless ETL job.
Unlocks with Learn Pass
PrepNPlaced Notes · included
The full notes library, one click away
SQL, Python, PySpark, Power BI, system design, interview handbooks and more — hundreds of pages of curated PDF notes on the PrepNPlaced Notes shelf, ready to read alongside the lectures here.
Handwritten guides, interview question banks, architecture carousels — the working materials behind the sessions, downloadable with Learn Pass or any active plan.