Cohort 4Register
Data Engineer Roadmap

Data Engineer Roadmap For SQL, Python, PySpark, Projects, And Interviews

A practical roadmap for learners who want to move from SQL and Python foundations into ETL, warehousing, PySpark, projects, resume proof, and interview readiness.

By Durgesh Yadav — Senior Data Engineer @ 7-Eleven · Updated 2 Oct 2026. Preparation guidance, not a hiring guarantee.

How long does it take to become a data engineer in India?

With consistent effort, a motivated learner reaches job-ready data-engineering skills in roughly 8–12 months: SQL and Python first (2–3 months), then Spark, cloud services and orchestration (3–4 months), then projects, resume work and interview practice. Career switchers from IT-adjacent roles often move faster through the fundamentals.

Guide

What To Learn And How To Practice

What is a data engineering roadmap?

A data engineering roadmap is the order in which to learn the skills the job uses: SQL and Python first, then data modelling and a warehouse, then Spark and one cloud platform, then orchestration and data quality, ending with projects you can explain in an interview. The order matters because each layer assumes the one before it.

SQL and Python: the base every later tool assumes
Data modelling and a warehouse: facts, dimensions, partitions
Spark and one cloud: processing data where it is stored
Orchestration and data quality: pipelines that run on schedule and fail loudly
Projects and interviews: work you can show and defend
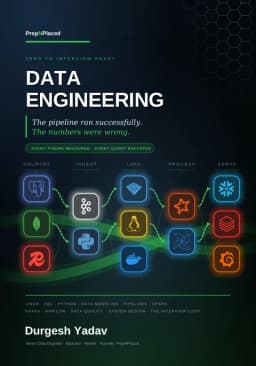
What does a data engineer actually do?

Data engineers build reliable paths for data to move from source systems into usable tables, pipelines, warehouses, and analytics-ready layers. Interviewers usually look for SQL depth, Python comfort, data modeling sense, and debugging clarity.

Ingest and clean data from multiple sources
Design tables and pipelines that analysts can trust
Monitor failures, data quality, freshness, and cost

Which skills should you learn first, and in what order?

Start with the skills that make every other tool easier: SQL, Python, data modeling, and pipeline thinking. Add warehousing, cloud basics, and Spark/PySpark after you can explain how data should be shaped.

SQL: joins, windows, CTEs, date logic, query reasoning
Python: files, APIs, data structures, pandas-style transformations
PySpark: DataFrames, partitions, lazy evaluation, joins, caching

Beginner project

Clean CSV/API data, load it into relational tables, and write SQL checks for missing or duplicate records.

Intermediate project

Build a batch ETL flow with staged, cleaned, and analytics-ready tables plus a small monitoring report.

What kind of projects create real resume proof?

A project is stronger when it shows source data, transformations, data quality checks, storage design, and a clear business question. Avoid only showing screenshots; explain tradeoffs and failure handling.

Raw to clean to modeled layers
Data validation and rerun behavior
README explaining schema, assumptions, and limitations

How do you run a 30/60/90 day preparation plan?

Use the first 30 days for foundations, the next 30 for projects and PySpark basics, and the final 30 for resume proof, mock interviews, and targeted revision.

Days 1-30: SQL, Python, data modeling fundamentals
Days 31-60: ETL project, warehouse basics, PySpark practice
Days 61-90: resume rewrite, mock interviews, project deep dives

How do you prepare for a data engineer interview, step by step?

Prepare in the order the rounds run and give SQL the most time, because it appears in almost every loop. Then Python for data work, what happens inside a Spark job, one cloud and its pipeline services, a way to answer design questions, and the story of your own project. Finish with mock interviews, which show you which round still needs work.

  1. Find out the loop: product companies and GCCs usually run four to six rounds, services companies two or three.
  2. Practise SQL every day: joins, window functions, CTEs and deduplication, explaining each query as you write it.
  3. Practise Python for data work: reading files and APIs, dictionaries, and pandas-style transformations.
  4. Learn what happens inside a Spark job: stages, shuffles, partitions, skew and broadcast joins.
  5. Pick one cloud and draw a pipeline on it from ingestion to the warehouse, including what happens when a step fails.
  6. Prepare one project you can explain end to end: the data, your design choices, what broke and what you changed.
  7. Run two or three mock interviews, then spend your remaining days on the round you did worst in.

FAQ

Common Questions

Is SQL enough to start data engineering?

SQL is the best foundation, but data engineering also needs Python, data modeling, pipeline thinking, and eventually distributed processing basics.

When should I learn PySpark?

Learn PySpark after you are comfortable with SQL, Python, and tabular transformations. It is easier when you already understand joins, partitions, and data shapes.

What projects should a beginner build?

Build a clean ETL project with raw data, transformations, data quality checks, modeled tables, and a README explaining design decisions.

How do I prepare for data engineer interviews?

Practice SQL, Python, pipeline design, data modeling, debugging scenarios, and project explanations. Use mock interviews to test clarity.

Should I mention every tool on my resume?

No. Mention tools you can support with a project, work example, or clear explanation. Unsupported keywords create interview risk.

How does PrepNPlaced help this roadmap?

Use Open Learning for foundations, courses for structured data training, Rewrite My Resume for proof-focused bullets, and AI Mock Interview for practice.

Next Step

Turn The Guide Into Practice

Use PrepNPlaced tools to turn this learning path into resume proof, targeted practice, and interview-ready explanations.

Explore Data Courses